Website Traffic in the Age of AI Crawlers: Lost Referrals, Blocking and Reliability
Published
SIAI Research Editorial*
*Swiss Institute of Artificial Intelligence, Chaltenbodenstrasse 26, 8834 Schindellegi, Schwyz, Switzerland
Abstract
The study examines how responses generated by language models and AI crawlers remove traffic from websites while simultaneously collecting their content without compensation. Data from the Pew Research Center, Cloudflare, HUMAN Security and TollBit show fewer clicks, more automated traffic and crawl-to-referral ratios in the thousands. The reliability of the responses remains problematic: the European Broadcasting Union's study found significant issues in 45 percent of answers on current affairs. Major publishers respond by blocking crawlers, so the most rigorously edited sources withdraw from the material that feeds the models. The study examines open-weight models, licensing agreements and Google's pilot payment programme and concludes that without verifiable crawler identity and an auditable valuation of contributions, every payment will remain a concession rather than an obligation.
1. Introduction - Website Traffic after the Answer Engine
The public debate about reducing website traffic usually describes a change of medium. Readers move their questions from Google's search engine to apps like ChatGPT, Gemini, and Perplexity. Google is losing share, and publishers are being asked to adapt to a new distribution channel, as they had previously adapted to Facebook and mobile devices. In this reading, website traffic is not lost, it just changes route. But the accounting doesn't work. A click on a Google results page resulted, in a significant percentage, in a website that could sell advertising, a subscription, or simply win a reader who would return. A language model's response usually gets nowhere because the reading is completed within the answer itself.
Available data points in this direction, with scale differences depending on the method. The IAB Tech Lab, the body that coordinates technical standards for digital advertising, estimates that AI-generated search summaries reduce publisher traffic by 20 percent to 60 percent, with losses of up to 90 percent on niche websites, and estimates the total loss of advertising revenue at about $2 billion.[1] This estimate aggregates third-party data and should be read as a range. More testable is the measurement by the Pew Research Center, which analyzed 68,879 searches of 900 U.S. adults in March 2025. Those who viewed an AI summary clicked on a traditional results link in 8 percent of visits, compared to 15 percent when no summary was displayed, while a link within the summary itself was clicked on only 1 percent of visits.[2] The metric is for a US panel and a single product at a specific point in time, but the direction is clear and coincides with what publishers are reporting.
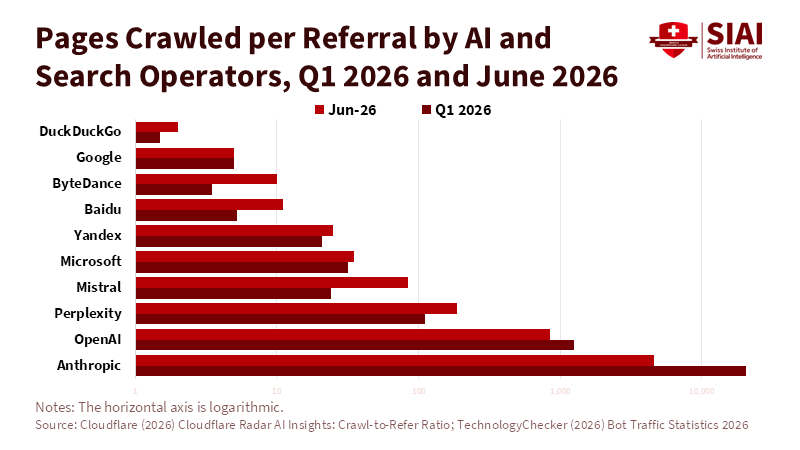
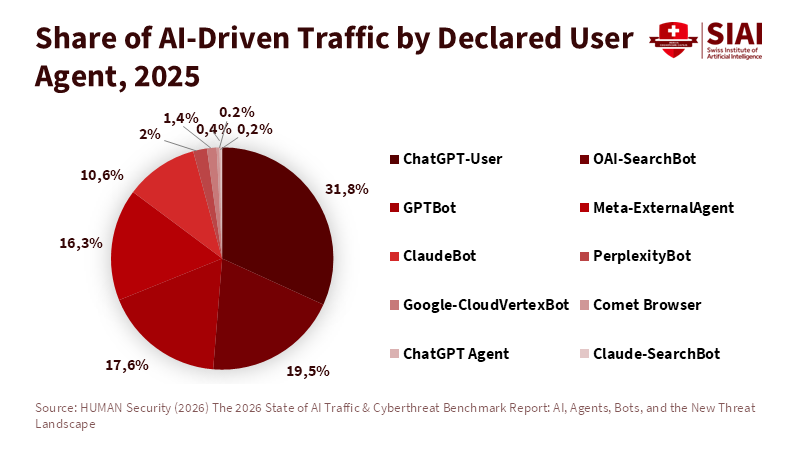
At the same time that people are thinning out, machines are increasing. According to Cloudflare data published by Fortune in July 2026, automated traffic surpassed human traffic in June of the same year and reached 57.5 percent of website requests. Cybersecurity firm HUMAN Security recorded a 7,851 percent year-over-year increase in traffic from AI agents performing actions such as link clicks and form filling, and a 597 percent increase in traffic from content scrapers.[3] Cloudflare also introduced an indicator that captures asymmetry more clearly than any percentage: the ratio of pages a platform crawls to back-referencing visits. For the week of June 19 to 26, 2025, the ratio for Anthropic was around 70,900 to 1, with the caveat that mobile apps do not indicate the referral source and that the ratio may therefore be overestimated.[4] Even with a brave correction, the distance from the logic of traditional search is enormous.
The present study argues that the issue is not limited to Google's loss. The removal of traffic is linked to two other developments that are usually discussed separately. The first is reliability: systems that replace click produce responses with measurable and persistent error rates, and the reader no longer has the source in front of them to judge it. The second is the reaction of publishers, who are increasingly blocking crawlers, causing the most thoughtful sources to withdraw from the very material on which the answers are based. Google hadn't done a great job, and language models don't necessarily make every query worse. The difference lies in the fact that the previous system, with all the distortions of search engine optimization, tied content quality to a fee, while the new one disconnects it.
The timing explains why the issue became urgent within three years. Google's AI Overviews summaries launched in the U.S. in May 2024[5] and expanded to dozens of markets, conversational apps gained real-time search functions, and as of 2025, autonomous browsing agents began to replace part of human browsing. Each of these steps transferred a piece of the reading from the website to the platform. The question that follows is practical before it becomes prescriptive: what exactly mechanisms that remove the traffic, and who pays the cost.
2. How AI Crawlers and Answer Engines Remove Website Traffic
Two mechanisms work in parallel and reinforce each other. The first acts on demand: the answer replaces the click. The second acts on supply: crawlers collect the content that will feed those responses, and the collection has its own cost for the site. In traditional search, the two sides were tied together. Google crawled a page to index it, and indexing existed to show a link that someone would click. The IAB Tech Lab quantified this split in November 2025: large language models perform between 250 and several thousand crawls before referring a visit, compared to about six for Google search, and have already removed up to 60 percent of traffic from referrals for publishers in the U.S.[6] It went as far as advising publishers to block crawlers.
Figure 1. AI crawlers take thousands of pages for every visit returned.
The loss is unevenly distributed. Major news organizations have direct traffic from loyal readers, subscriptions, and the ability to negotiate. A niche blog lives almost exclusively from search, because no one types in the address of a travel blog by heart when looking for where to eat in Lisbon. The IAB Tech Lab cites the case of the travel blog The Planet D, which recorded a 90 percent drop in traffic in the initial phase of Gemini's integration into search, and links it to the concentration of the advertising market: according to the IAB and PwC 2024 report, 80.8 percent of online advertising revenue ends up in the ten largest companies.[7] When distribution goes through responses controlled by a few platforms, the bargaining position of the independent creator deteriorates from an already weak starting point.
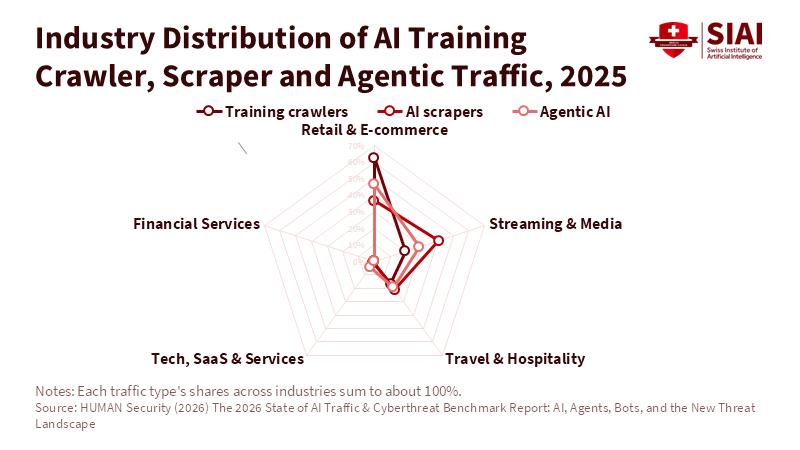
Figure 2. Media is the top target of live AI scraping.
The second mechanism became visible in an almost comical way, before becoming annoying. From the fall of 2025, websites of all sizes began to see in their statistics thousands of "visitors" from Lanzhou, an industrial city in northwest China with no reputation as a technology center, with some of the traffic routed through Singapore. WIRED recorded in February 2026 the case of a website from Bogota about paranormal phenomena, written in a mixture of Spanish and English, in which China and Singapore had become the source of more than half of the traffic in a year, with an average visit duration of zero seconds. According to the Analytics.usa.gov platform, Landshow accounted for 14.7 percent and Singapore accounted for 6.6 percent of visits to U.S. federal government websites in the previous quarter.[8] Who is behind the traffic remained open. The geographical attribution of an IP address shows where the infrastructure is registered, not necessarily who is using it, and WIRED itself noted that experts could not explain why Landshow appears so systematically. The assumption that this is a collection of training data is plausible, but it is not proven.
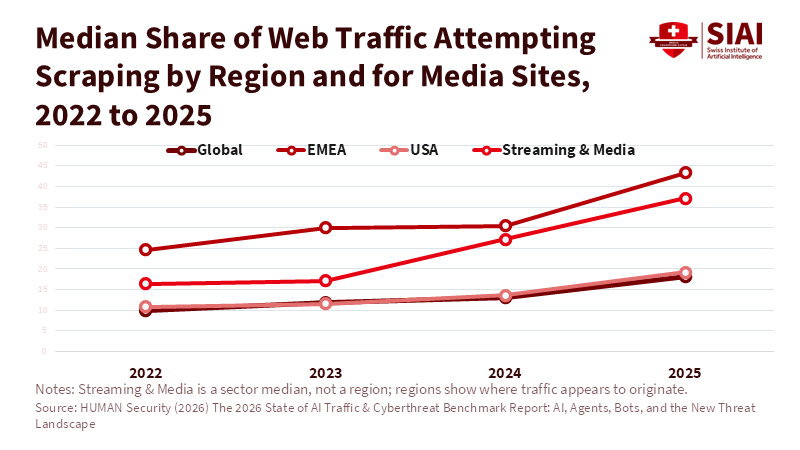
Figure 3. Scraping has more than doubled on media sites since 2022.
The scale of the phenomenon is not limited to one city. TollBit, which tracks the movement of AI robots on publisher websites, counted in the fourth quarter of 2025 one robot visit for every 31 humans, up from one for every 200 at the beginning of the same year.[9] For small websites, the consequences are tangible and have a price. The Breached.Company team described how in January 2026 one of its websites was removed from the Ezoic advertising network without explanation, and how the investigation led to the same pattern of traffic from China and Singapore. An administrator citing the same analysis recorded 127,000 daily bot visits at its peak, dropping to 2,000 after blocking entire autonomous systems belonging to Chinese cloud providers.[10] When an ad network sees hundreds of thousands of zero-length sessions, it reasonably concludes that the publisher is inflating its numbers, and the publisher is penalized for a move it didn't request.
The picture is complicated by the fact that part of this "traffic" does not even touch the website. Twenty-First Digital, which advises publishers on measurement issues, distinguishes two scenarios. In the first, automated systems actually load the page, the Google Analytics measurement code runs normally, and the session is recorded, so the traffic also appears in the server files. In the second, fake signals are sent directly to Google Analytics, without any contact with the website, and no server-level blocking can stop them.[11] The practical result is that the publisher simultaneously loses readers and the ability to count which readers are left. Engagement rates, reading time and geographical distribution, the quantities by which it decides what to write and how to sell it, are distorted.
It would be a mistake to read the phenomenon as exclusively Chinese. Many publishers are seeing similar waves from Ashburn, Virginia, the suburb of Loudoun County where the world's densest concentration of data centers is located and where Amazon Web Services, Microsoft, and Google maintain large facilities. Geolocated traffic in Ashburn is almost always cloud infrastructure traffic, and that includes the declared crawlers of American AI companies, undeclared agents, monitoring tools, and VPN networks, all mixed under the name of a suburb with a few tens of thousands of residents. The distinction between American and Chinese origin matters to the jurisdiction, as will be seen below, but for the publisher the result is the same: the people who were reading are removed from the response, and in their place appear machines that consume bandwidth, distort the measurements and take the text.
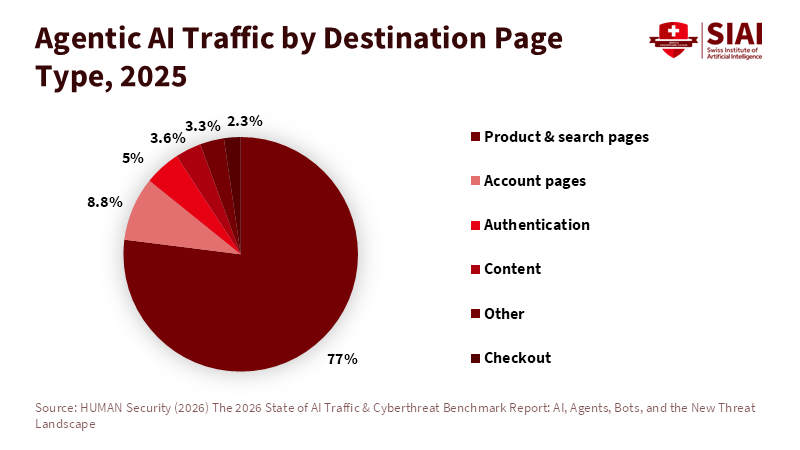
Figure 4. AI agents now reach accounts and checkouts, not just pages.
If all this were simply switching from one search medium to another, the damage would fall mainly on Google and would be a matter of competition. This assumes that the other participants, the creators, the readers and even the providers of the models themselves, are in the same or better position than before. That is what needs to be checked.
3. Who Gains from Models Trained on Website Data
A simple profit and loss account shows that the losers are more than one. Search engines are losing clicks, and Google itself is replacing results pages that brought ads with summaries that bring them harder. Content creators are losing traffic with the mechanisms described. Readers are gaining speed, but they cannot know if the answer they are reading is correct. The last leg is the least visible and perhaps the most serious, because it concerns people who have no financial connection to the dispute between publishers and platforms.
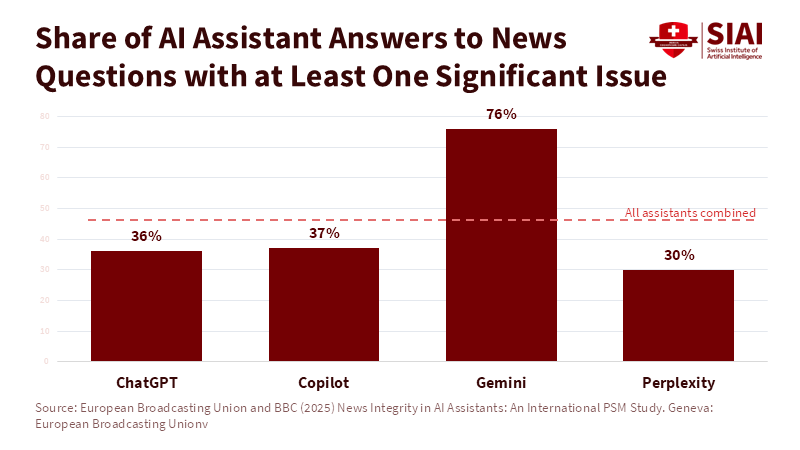
The largest assessment of AI assistants in news to date was coordinated by the European Broadcasting Union and led by the BBC and published in October 2025. Twenty-two public broadcasters from 18 countries, in 14 languages, evaluated more than 3,000 ChatGPT, Copilot, Gemini, and Perplexity responses to current affairs questions. 45 percent of responses had at least one major issue, 31 percent had serious source rendering issues, meaning sources that were missing, misleading, or incorrect, and 20 percent had serious accuracy issues, with made-up details and outdated information. Gemini had significant issues in 76 percent of responses, mostly due to source attribution.[12] The significance of the outcome depends on how many already rely on these tools. The Reuters Institute's Digital News Report 2025 recorded that 7 percent of those who update online use AI assistants weekly for news, a figure that rises to 15 percent for those under 25.[13] The rates are small in absolute terms, rising precisely at the ages that will shape the habits of the next decade.
Figure 5. Gemini's answers carried significant issues more than twice as often as ChatGPT's, Copilot's or Perplexity's.
Columbia University's Tow Center for Digital Journalism had come to a similar conclusion with a different method. It tested eight search tools based on language models asking them to identify the title, publisher, date, and address of articles from snippets, and found that overall they answered more than 60 percent of queries incorrectly. Paid versions of some tools gave incorrect answers with greater certainty than free ones, and several tools built links that led nowhere.[14] The finding for certainty is critical. A tool that says "I'm not sure" transfers to the reader the responsibility of checking. A tool that answers incorrectly in the same tone that answers correctly removes it.
It could be assumed that the problem is solved when the model works on specific documents rather than from its "memory." A study from Northwestern University and the University of Minnesota tested exactly this scenario: it gave ChatGPT, Gemini, and NotebookLM a corpus of 300 documents about the legal and regulatory dispute surrounding TikTok in the U.S. and asked for journalistic research-type tasks. 30 percent of the responses contained at least one hallucination, with about 40 percent for ChatGPT and Gemini and 13 percent for NotebookLM. Most of the errors were not invented entities or numbers. It was what the authors called interpretive overconfidence: the models added characterizations of sources that the sources did not support and converted opinions attributed to specific actors into general findings.[15] For a publisher this carries particular weight. An opinion article arguing that a policy will fail may appear in response as a given that the policy failed, without a name, without a link, and without the reservation that the author had written.
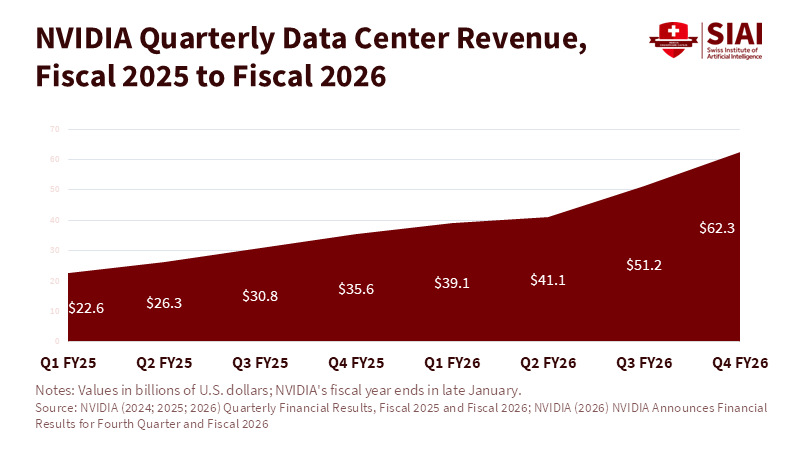
If readers come out uncertain and creators lose, the obvious next step is to look at model providers as beneficiaries. The available financials don't easily support this picture. According to shareholder documents cited by The Information, OpenAI consumed $3.7 billion in cash flow in the first quarter of 2026, with revenue of $5.7 billion over the same period.[16] Each answer has a computation cost, and in much of free use that cost is not covered by revenue. The bleeding is, quite literally, in tokens. Margin accumulates upstream, in hardware and infrastructure. Nvidia reported revenue of $130.5 billion for the fiscal year ended January 2025 of which $115.2 billion came from the data center division.[17] In this chain, those who sell chips, data center space, and paid development work are in a much better position. The other links, from the editor of a blog to the provider of the model that subsidizes the answers, are either losing or betting on future profitability.
Figure 6. Hardware revenue kept climbing while model makers burned cash.
The strongest counterargument deserves serious consideration. Summaries and conversational responses save time, give unqualified people access to explanations that would otherwise require hours of reading, and serve queries for which no one really needed to visit a page. Click-free search, after all, didn't start with AI. Google's answer snippets and knowledge boxes kept users on the results page for years, and Pew itself recorded that about two-thirds of searches ended up without clicking on a result, regardless of the summary display. The argument correctly describes a portion of the value to the user. It doesn't answer two things: that the summary almost doubles the loss for queries where the user would step somewhere, and that the value for the user is produced with material that someone else paid to exist.
This leads to the question of whether the models can be made reliable enough for the replacement of the source to be acceptable. The explanation given by researchers at OpenAI and Georgia Tech in September 2025 is enlightening and less reassuring than they might have liked. Hallucinations, they argue, arise as binary classification errors under the natural statistical pressures of pre-training: where incorrect propositions cannot be distinguished from true ones, the model will produce plausible falsehoods. They persist because most evaluations score in a way that rewards guesswork over assuming uncertainty. For events without an internal pattern, such as a date of birth, the hallucination rate of a baseline model is expected to be at least as much as the percentage of events that appear just once in the education.[18] Duke University Libraries, in a January 2026 analysis, came to a compatible conclusion: hallucinations thicken where data is sparse, contradictory, or of low quality, and the model does not inherently know which sources are reliable.[19]
The scarcity of data on a topic therefore increases errors. But it is not their root. A linguistic model produces the most likely continuity of a text based on statistical regularities, not a claim that has been tested against some representation of the world, and this difference is not eliminated by adding more texts. It is improved by retrieving sources, by training that rewards abstention, and by better calibration, but it remains a property of the method. Herein lies the essential difference from Google's results page, which was full of inadequacies. In front of a list of ten links, the reader decided which one to open, saw the name of the publisher, held a rudimentary judgment about whether a medical question was better answered by a hospital or by a forum. In front of an answer, the choice has already been made by the system, and the reader simply reads. The rate of 1 percent of click-through visits within the summary shows how rarely the reader returns to the source to check. The responsibility for verification shifts from the reader to a system that does not bear it, neither legally nor commercially.
4. Why Publishers Lack Control over AI Use of Their Content
The word "correction" assumes that there is someone who can intervene and a mechanism through which the intervention reaches the result. For hallucination, the providers themselves talk about reduction, not elimination. OpenAI, presenting the analysis discussed above, stated that GPT-5 has significantly fewer hallucinations, especially when it uses reasoning, that they still occur, and that they remain a fundamental challenge for all major language models.[20] In a system that answers hundreds of millions of queries a day, a small error rate is a large absolute number of incorrect answers, and there is no way for the reader to know which category the one they are reading belongs to.
For the remuneration of creators, the answer is even less encouraging, and a comparison with the previous regime helps to show why. Google didn't pay publishers for indexing. But it sent them traffic, and the traffic was converted into revenue through advertising or subscriptions. The race for the first page of results had its pathologies, from content farms to texts written for algorithms instead of humans, but it maintained a basic connection: better content was more likely to be read, and reading had value for whoever wrote it. The answer engine maintains the first half relationship, since it selects and leverages useful content, and cuts the second.
An inability to check is what makes the situation different from a simple decrease in revenue. A publisher cannot decide whether their text will be used in a response that falsifies it. They cannot choose in which responses and next to which other sources to appear. If a response attributes something they did not write, there is no correction mechanism equivalent to a correction request to a newspaper. If they update an article because the information has changed, they cannot ask the provider to replace the old version that was already absorbed in the training. Often they do not even know if and when its content was detected. Since 2 August 2025, the EU AI Act has required providers of general-purpose models to publish a summary of their training content, using a template the European Commission issued on 24 July 2025. The template asks for a narrative summary of sources and a reference to the most important domain names from which data was collected, not a per-site archive of what was collected and when.[21] It's a market-level transparency step. For the individual website, almost nothing changes.
The tool that is supposed to give control, the robots.txt file, is a polite request that nothing enforces. Cloudflare published an analysis in August 2025 that Perplexity used undeclared crawlers, changing IP addresses and browser identities, to access websites that had explicitly requested not to be crawled.[22] A January 2026 Press Gazette analysis noted that robots.txt guidelines can be ignored or bypassed through third-party companies that collect content on demand, and that the IAB Tech Lab, reviewing much of the publishers' guidelines, found a host of typos and incorrect settings that render them ineffective. The same analysis also identifies a structural problem with Google: the Google-Extended option allows the publisher to opt out of Gemini training, but not from using the content in AI Overviews summaries. To avoid summaries, a publisher would have to block Googlebot, i.e. disappear from search.[23] Crawl for search and crawl for responses are tied, and the publisher can only deny both together.
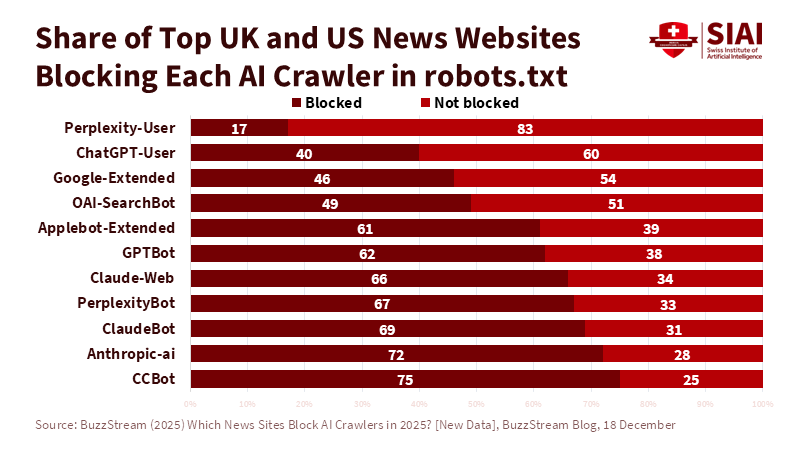
Under these circumstances, blocking became the dominant strategy of major publishers. In February 2024, 61 of the 106 largest news sites in the UK and the US were blocking at least one AI crawler.[24] In January 2026, Buzzstream platform's analysis of nearly a hundred top websites in the two countries found that 79% were blocking at least one training tracker and 71% were blocking crawlers that retrieve real-time content for responses. Among the 50 largest, 34% blocked all crawlers examined, with the BBC, the New York Times, the Daily Mail, the Telegraph, the Associated Press and the Wall Street Journal among them, while Anthropic's training crawler was the least allowed, with access to just eight of the fifty. The Telegraph explained its position in terms of exchange: almost no value returns, language models are not designed to send traffic, and companies are not willing to pay for the content they were trained on. Belgian public broadcaster VRT, which participated in the European Broadcasting Union study, used its findings to justify restricting AI assistants' access to its news content. At the infrastructure level, Cloudflare started on July 1, 2025, by default blocking AI crawlers for the new domains it serves, while offering a pilot bill-per-crawl system.[25] Millions of websites that had never opened a robots.txt file found themselves blocked without deciding for themselves.
Figure 7. Publishers block training bots far more than retrieval bots.
The academic literature on content "control" in relation to artificial intelligence gives little help to the editor who sees their text absorbed. A typical proposal, presented at a workshop at the NeurIPS 2025 conference, describes a multi-agent system, with design, production, revision, integration, and protection agents, that incorporates subtle watermarks during the production process itself.[26] The approach is useful for the traceability of material produced with AI tools. But it protects the output of a creator who already uses such tools, and offers nothing to the author of a text written by a human, openly published, and collected for training. The problem of input remains untouched.
Here the two threads of the study, traffic and credibility, are tied together in a loop that has no obvious output. The sources that invest the most in checking their data, the big news organizations, the public broadcasters, the specialized publications with paid editors, are the ones that exclude first, because they have the resources and the bargaining power to do so. The more they withdraw, the greater the part of the answers is based on what remains open: on websites that live off search engine optimization, on republications, on copies. The Tow Center found that some tools displayed content from publishers that had blocked their crawlers, drawing it from republished versions on other sites. Blocking, in other words, does not fully protect either the publisher, who sees their material circulating without attribution, or the reader, who gets a second-hand response. And for the traffic that is geolocated in Lanzhou or Singapore, where it is not even clear who is crawling, there is no counterparty to negotiate, no competent authority to complain or a standard that is committed to respecting, so the publisher resorts to the only mechanism available, the blocking of entire networks, at the cost that along with the bots, it also blocks any real reader from the region who happens to pass through the same providers.
5. What Needs to Change: Open Weights and Payment for Creators
Two directions emerge from the analysis, and none is sufficient on its own. The first concerns the nature of the product. A general-purpose language model, with the exception perhaps of its capabilities in code, where companies have invested extensively in their own data and in human labeling, is largely a distillation of texts written by millions of people without being asked. From this perspective, the model is a common product and not an exclusive property, and the minimum obligation of anyone who trains it is to make it available with open weights, if not as fully open software with published training data. The argument has gained practical weight. In January 2025, DeepSeek launched the R1 reasoning model with open weights under the MIT license, proving that a model competitive with closed weights can be freely available.[27]
Open weights, however, solve a different problem than that of the creator. They return value to the public in the form of access: researchers can control the behavior of the model, public organizations can host it without depending on a provider, small businesses can adapt it. They don't pay any editor, they don't give them control over the use of their text, and they make further use even more undetectable, since a model with open weights can be embedded anywhere. Nor do they reduce hallucination, which, as it turned out, are a property of the method. There is a more uncomfortable side: the very idea that the written production of humanity is a common good can be used as a justification for the very uncontrolled collection described in the first chapter. Whether openness compensates for expropriation or simply makes it more acceptable depends on what else accompanies it.
The second direction is payment, and its problem is who gets paid. The licensing agreements that have become known concern organizations with pooled records and bargaining power. Reddit agreed with Google in February 2024 to make its content available for training for about $60 million per year, according to Reuters, followed by a deal with OpenAI in May of the same year.[28, 29] But the texts were written by Reddit users, who received nothing. In the book space, the settlement in the Bartz v. Anthropic case amounted to $1.5 billion. That's about $3,000 for each of about 500,000 works.[30] The case showed that using a work for training can gain a price when asked for by a court, but it involved books that had been acquired by pirate libraries and protected authors with publishers behind them. A single blog editor has neither the resources for a corresponding trial nor a catalog of works large enough to interest a buyer. If the licensing market remains a large archive market, independent online writing will continue to feed models for free until it ceases to be produced.
The most advanced step towards payment at the individual page level has been taken, perhaps unexpectedly, by Google. According to Digiday in September 2026, the company is scaling up a pilot program within Search Console that pays publishers when their content contributes "significantly" to Gemini, AI Overviews, and AI Mode responses. Participants see a monthly amount of earnings with no explanation of how it's calculated, the program has attracted more interest from small and medium-sized publishers than large groups, and is expanding beyond news. Publisher executives described the bids as low, and one of them warned that participation could weaken publishers' bargaining position, since Google will be able to claim that it is already compensating.[31] The logic of the program, payment per contribution rather than per file, is exactly what a small creator needs. Its implementation, with unilateral valuation, non-transparent form and participation only by invitation, leaves the power to set the price in the same place it was before.
Other schemes have emerged around this initiative, with a different philosophy. Cloudflare introduced a per-crawl fee in 2025, which turns blocking into a price. The IAB Tech Lab formed a working group on AI-powered content utilization protocols, which included Google, Microsoft, and Meta, while OpenAI, Anthropic, and Perplexity, according to the agency, did not respond. The Really Simple Licensing standard, introduced in September 2025 with the support of Reddit, Yahoo, and Medium among others, it allows a website to declare in a machine-readable format the licensing terms of its content.[32] In the Internet Engineering Task Force, the Working Group on AI Usage Preferences is working on a common vocabulary by which a website can distinguish between education, search, and other uses.[33] None of this is mandatory for anyone crawling, and this is their common limit.
Figure 8. Firms absent from licensing talks generate most AI bot traffic.
The necessary changes are distributed among different actors, and the confusion of roles is part of the problem. Companies that develop models can, without any legislation, publicly separate their crawlers by purpose, cryptographically sign their requests so that their identity is verified, give each website access to the file of crawls concerning them, and open a correction channel for claims attributed to a specific source. They can also apply what OpenAI's own analysis suggests, i.e. scoring that rewards abstention when sources are insufficient and make visible attribution with a link by default to any response based on retrieved content. Google and other answering engines experimenting with payments should publish how the contribution is measured, show data by page address and open the programmes on any website that meets the minimum criteria, without an invitation. Publishers and independent creators have an interest in organising themselves into collective licensing bodies, along the lines of music collecting societies, because only pooled producers acquire a catalogue of commercial interest. The IAB Tech Lab has argued that without scarcity there is no market, and concerted exclusion is the only way to create scarcity, but at the risk of being seen by competition authorities as a cartel.
Public intervention is justified where the market cannot coordinate on its own, not in price setting. A register of crawlers with a mandatory verifiable identity, the legally binding nature of machine-readable opt-out statements that will result from the Internet Engineering Task Force standards, and the right of every website to ask a provider if and when it has collected its content, as an extension of the European summary model, are measures that no single company has any incentive to adopt first. Competition authorities have reason to consider linking crawling-to-search and crawling-to-responses in the case of Google, because that's where the publisher has no real choice. For traffic coming from jurisdictions where none of this is applicable, transnational cooperation is the only avenue, and progress in this area has so far been minimal.
6. Conclusion - Content and Computation Both Carry a Cost
Artificial intelligence is not free. It is calculated on chips, energy, data centers and salaries, and the companies that offer it today pay more than they receive. Nor is content free. It was paid for by someone, with advertising that relied on readers, with subscriptions, with the unpaid time of a person writing about a topic they knew well. The transition from the results page to the answer page maintained the cost of the computational side and implicitly removed the mechanism that covered the cost of the content.
The analysis showed that the damage is not limited to Google. Creators lose readers and the ability to count those who remain. Readers get answers with errors that are measured in double-digit percentages, formulated with certainty that does not correspond to their accuracy, and without the source in front of them. Sources with the strictest control are withdrawn, and answers are increasingly based on what is left open. Deterioration of credibility and loss of traffic are aspects of the same process.
Open weights return public access, not remuneration. Licensing agreements pay those with large files. Google's pilot program is the first to pay per contribution, with terms it unilaterally sets. Whether these will evolve into an working system or remain symbolic gestures cannot yet be judged.
The minimum necessary point is clear. Without verifiable identities of crawlers, binding exclusion statements, and a third-party verifiable contribution assessment, each payment scheme will function as a concession rather than an obligation, and independent writing will continue to feed systems that answer with certainty, often incorrectly.
References
[1] IAB Tech Lab (2026) LLM Content Ingest API Initiative. New York: IAB Technology Laboratory.
[2] Chapekis, A. and Lieb, A. (2025) Google users are less likely to click on links when an AI summary appears in the results. Washington, DC: Pew Research Center, 22 July.
[3] Fortune (2026) 'Turns out Dead Internet Theory was right: AI agents are eating the Web, growing by nearly 8,000% and rewiring the Internet's business model', Fortune, 23 July.
[4] Belson, D. and Rhea, S. (2025) 'The crawl before the fall of referrals: understanding AI's impact on content providers', The Cloudflare Blog, 1 July.
[5] Google (2024) 'Generative AI in Search: Let Google do the searching for you', The Keyword, 14 May.
[6] Mumbrella (2025) ''Why buy the cow?' IAB Tech Lab warns publishers over AI traffic losses', Mumbrella, 19 November.
[7] IAB Tech Lab (2025) Dude, AI ate my traffic. New York: IAB Technology Laboratory.
[8] Yang, Z. (2026) 'A wave of unexplained bot traffic is sweeping the web', WIRED, 12 February.
[9] Levinson, A. (2026) 'A surge of strange bot traffic from China has website owners alarmed. Here's what it means for your data', Inc., 13 February.
[10] Breached.Company (2026) We got hit by the mysterious Lanzhou bots: here's everything you need to fight back, 17 February.
[11] Twenty-First Digital (2026) Seeing a spike in direct traffic from Gansu, China? Here's what to do next.
[12] European Broadcasting Union and BBC (2025) News Integrity in AI Assistants: An International PSM Study. Geneva: European Broadcasting Union.
[13] Newman, N., Ross Arguedas, A., Robertson, C.T., Nielsen, R.K. and Fletcher, R. (2025) Reuters Institute Digital News Report 2025. Oxford: Reuters Institute for the Study of Journalism.
[14] Jaźwińska, K. and Chandrasekar, A. (2025) 'AI search has a citation problem', Columbia Journalism Review, 6 March.
[15] Hagar, N., Agustianto, W. and Diakopoulos, N. (2025) Not wrong, but untrue: LLM overconfidence in document-based queries. arXiv:2509.25498.
[16] Woo, E. (2026) 'OpenAI burned $3.7 billion in first three months of 2026', The Information.
[17] NVIDIA (2025) NVIDIA announces financial results for fourth quarter and fiscal 2025. Santa Clara, CA: NVIDIA Corporation, 26 February.
[18] Kalai, A.T., Nachum, O., Vempala, S.S. and Zhang, E. (2025) Why language models hallucinate. arXiv:2509.04664.
[19] Duke University Libraries (2026) 'It's 2026. Why are LLMs still hallucinating?', Duke University Libraries Blogs, 5 January.
[20] OpenAI (2025) Why language models hallucinate. San Francisco, CA: OpenAI, 5 September.
[21] European Commission (2025) Explanatory Notice and Template for the Public Summary of Training Content for General-Purpose AI Models. Brussels: European Commission, 24 July.
[22] Cloudflare (2025a) 'Perplexity is using stealth, undeclared crawlers to evade website no-crawl directives', The Cloudflare Blog, 4 August.
[23] Tobitt, C. (2026) 'Eight in ten of world's biggest news websites now block AI training bots', Press Gazette, 22 January.
[24] Maher, B. (2024) 'Revealed: Which of the top 100 UK and US news websites are blocking AI crawlers', Press Gazette, 27 February.
[25] Cloudflare (2025b) Cloudflare just changed how AI crawlers scrape the internet-at-large; permission-based approach makes way for a new business model. San Francisco, CA: Cloudflare, 1 July.
[26] Khan, H. and Asif, S. (2026) Generative AI agents for controllable and protected content creation. arXiv:2601.12348.
[27] DeepSeek-AI (2025) DeepSeek-R1: Incentivizing reasoning capability in LLMs via reinforcement learning. arXiv:2501.12948.
[28] Reuters (2024) 'Exclusive: Reddit in AI content licensing deal with Google', Reuters, 22 February.
[29] OpenAI (2024) OpenAI and Reddit partnership. San Francisco, CA: OpenAI, 16 May.
[30] Bartz v. Anthropic PBC (2025) No. 3:24-cv-05417, United States District Court for the Northern District of California, class settlement.
[31] Digiday (2026) 'Google rolls out pay-per-value AI licensing program to publishers', Digiday, September.
Generational Gap in AI: Why Age Alone Does Not Explain Adoption
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
Modified
Age alone does not explain the generational AI gap
Exposure and institutional support shape different adoption paths
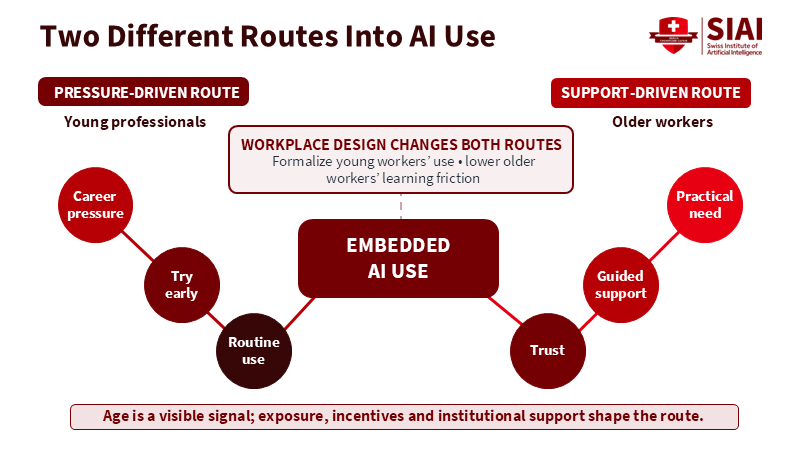
Younger and older users face different pressures to adopt
The generational gap in AI is easy to describe and harder to explain. In 2026, 66 percent of Americans aged 18 to 29 said they were using AI chatbots, compared to 23 percent of those aged 65 and older. The difference in self-confidence was even greater. Almost one in three under 30 said they were very confident in their ability to use chatbots, while among those 65 and older the figure was just 6 percent. It's tempting to think that age explains almost everything. But this reading leaves out how familiarity with a technology is acquired. Age coincides with different professional exposure, different digital experiences, different needs and different entry points. The gap is real. The mechanism that creates it is much less simple.
The Generational Gap in AI Starts With Exposure
Age initially acts as a historical advantage or disadvantage. A 25-year-old in 2026 has spent almost his entire conscious life in environments where digital services, search engines, applications and constantly changing interfaces are considered normal. A 70-year-old has spent much of his professional life before this condition. This does not determine the latter's ability to learn AI. But it does determine how many previous steps are taken for granted when a new tool appears. Using a chatbot requires less technical knowledge than many previous digital systems, but it still requires comfort with accounts, settings, online search, source evaluation and personal data management.
Daily exposure reinforces this difference. Younger people encounter AI within work, search services, smartphones and tools they already use. Older people, particularly those who have left the labor market, have fewer mandatory contacts with such systems. In an international survey of people aged 60 to 85, those who remained employed used AI about three times more than those who had retired. This shifts attention from age to exposure. The calendar year of birth remains relevant, but part of its effect runs through work. The business, the colleague, the new process and the need to complete a particular task create recurring touchpoints that a retiree may simply not have.
Older Users’ Uncertainty Is Not Simple Resistance
The data for older users initially seems to confirm the picture of resistance. In the U.S., 77 percent of those aged 65 and over were not using chatbots at the beginning of 2026. Only 19 percent were using ChatGPT, compared to 61 percent in the 18 to 29 age group. Older people were also much more likely to state uncertainty about what AI will do in society or in their own lives. If the generation gap is only read through these percentages, the easy explanation is that the technology encounters an age resistance that is difficult to change.
The picture becomes different when the reasons are examined. In a global survey of older adults, 41 percent cited potential misuse of personal data as a barrier, 34 percent didn't know which AI tools to use and 23 percent didn't know where to start. Only 15 percent said they weren't interested in learning more. 44 percent preferred easy-to-use guides that they could follow at their own pace and nearly one in three preferred online training from AI providers. These aren't responses from people who have collectively rejected the technology. They describe an entry problem. When the initial cost of learning is higher and the practical benefit isn't yet apparent, not using it can feel like resistance when in fact it's waiting.
There is also an older clue that is worth preserving. Research around the adoption of previous technologies by older adults has found that utility, convenience and confidence often explained more than just a negative attitude towards technology. Older users could have a positive view when a tool solved a clear problem, despite concerns about safety and reliability. AI does not remove this mechanism. It makes it more important because much of its value is only realized after a little practical use.
Younger Adults Use More Without Trusting More
The opposite error occurs when the high use of young people automatically translates into enthusiasm. Americans under 30 are the most frequent users of many AI tools, but in 2026 they were also the age group with the most negative assessment of the future social impact of the technology. 48 percent expected a negative impact on society and 37 percent a negative impact personally. In those 65 and older, the corresponding percentages were lower, although the uncertainty was greater. Use and acceptance therefore do not necessarily go together. One may consider a tool necessary and at the same time not trust the direction it is leading.
This is of institutional importance. For new employees, AI appears at a stage where there is not yet a large stock of professional experience to act as a protection. Workplaces are increasingly making AI competence part of ordinary professional participation, even among employees who remain wary of the technology. This pressure explains why the behavior of young people should not be read as pure technophilia. An employee may use generative AI every day because the productivity expected in the role has already changed or because he thinks that without this skill it will be more difficult to get the next position.
The same makes the concept of "digital native" problematic. Comfort with apps and platforms does not equate to the ability to assess the quality of an answer, understand when a model produces an incorrect result, or make the right judgment about what data should not be entered into an external system. Young people usually start with lower psychological and operational costs of use. This does not mean that they start with integrated AI literacy. Frequency of use measures exposure. It does not measure proficiency in itself.
Figure 1: Different pressures can lead both generations toward embedded AI use.
Institutions Can Widen or Narrow the Gap
If age were the deciding factor, the possibilities for intervention would be limited. But the large difference between employees and older retirees shows that the environment can significantly shift behavior. An organization that introduces AI along with hands-on training, secure accounts, clear rules for data and human support reduces first-time costs. An organization that simply buys a tool and assumes that employees will learn on their own leaves the advantage to those who already had reason to experiment. In this way, a difference in previous experience turns into a larger difference in productivity.
The same logic applies outside of work. As banking, health, customer service and public services integrate AI, access isn't just ensured because there's a chatbot on the screen. For a savvy digital user, the conversational interface can reduce complexity. For someone who is already worried about scams, personal data, or incorrect answers, it can create a new level of uncertainty. The ability to switch to human service, clear explanations for data usage and training on real needs are therefore part of the technological infrastructure itself, not external social benefits.
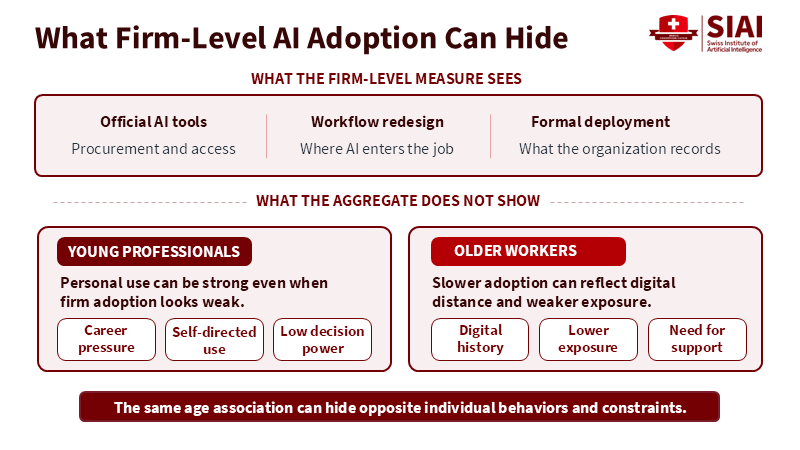
This also changes how generational comparisons should be read. If two age groups have different uses, the next question is not just which is more receptive, but which group has an employer-provided account, which has a colleague who can show proper use, which performs tasks where the outcome is immediately apparent and which has to bear the cost of learning without a clear benefit. Once these variables are in the picture, the generational gap in AI starts to look more like an institutional effect manifested through age.
Figure 2: Aggregate adoption can conceal very different barriers and incentives by age.
Age Is a Signal, Not the Cause
Age remains a useful indicator. It would be just as wrong to ignore it because other factors matter. Past digital experience has been accumulating over decades and the differences in exposure are real. Older adults show lower use and much lower confidence in today's tools. Younger people use AI more and encounter technology more often at work and in everyday digital life. This distribution isn't going to disappear just because interfaces are getting easier.
Where correction is needed is in causality. For an organization knowing that an employee is 62 years old does not tell if they use AI every day, if they work in a high-exposure industry, whether they have received training, or if they already have strong digital skills. Similarly, being 23 years old does not guarantee that they understand the limits of a model or that they can properly integrate AI into a professional process. Age acts as a short indicator for many different experiences that often coincide. The more institutions deal with these experiences directly, the less accurate age becomes as a predictor of behavior.
This is perhaps the most useful point for the next phase of adoption. The generational gap in AI will not close because today's young people will gradually replace today's older ones. Each new technological phase creates new groups with different levels of exposure and different adaptability.If familiarity is acquired mainly through work, then those outside it will continue to lag behind. If training remains informal, those who are already confident will learn faster. Age will continue to show in the data, but the size of the difference will depend largely on the environment created around the tool.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
AI Accountability in Politics Requires Continuous Monitoring
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
Modified
Deepfakes are only the visible layer of political AI risk
Chatbots increasingly shape how voters receive political information
Continuous monitoring makes changing AI behaviour visible and accountable
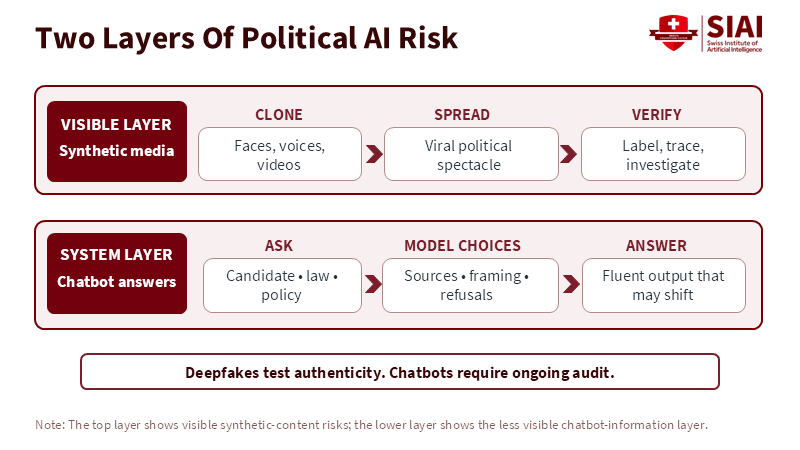
A conservative political action committee named Citizens for Sanity released a series of AI-generated videos in June 2026 mocking Texas Senate candidate James Talarico dressed as a governess and singing a parody of a show tune about transgender children, and by the time PolitiFact measured the campaign's reach later that month, the ads had garnered about 1.4 million impressions on Facebook alone, according to Meta's own advertising data. No one who watched the clip mistook it for an actual recording. The trick was the message, meant to be communicated as a spectacle rather than to be believed as a fact. This distinction, between content created to deceive and content created to be identified as fake and still doing political work, has absorbed most of the attention paid to AI and elections this cycle, while a quieter and much larger change, in how tens of millions of voters get their political information from chatbots in the first place, has prompted much less scrutiny. This second level is where AI accountability in politics needs to begin.
Deepfakes Are the Visible Layer of AI Political Risk
The Talarico ad wasn't an isolated trick. Citizens for Sanity posted six AI-generated videos over several days mocking the Democratic Senate candidate, a campaign that PolitiFact journalist Loreben Tuquero spotted in the Meta ad library and found running alongside a Texas law that bans political deepfakes within thirty days of the election and treats violations as a Class A misdemeanor. Adrian Shelley, director of the advocacy group Public Citizen in Texas, told Tuquero that the tools had crossed a line: campaigns no longer needed a movie studio to depict an opponent doing or saying anything, just one subscription and an afternoon. In the race for governor of Massachusetts that same year, Republican Brian Shortsleeve posted a fabricated audio clip mimicking Democrat Maura Healey, a revelation that did nothing to slow down its online circulation.
Two years before the Talarico ad aired, during the 2024 New Hampshire primary, an AI-generated imitation of President Joe Biden’s voice told voters to save their ballots for November. The Federal Communications Commission fined Kramer six million dollars in September 2024, and Loyaan Egal, who heads the law enforcement office, said the incident threatened the foundations of democratic elections. New Hampshire prosecutors separately charged him with felony voter suppression. What Talarico's ads, Shortsleeve clip, and Kramer's Robocall share is not partisanship but a cost curve: synthetic political content is now cheap enough for any campaign, super PAC, or lone agent to produce, which is precisely why the ability to reliably vouch for what's real has become rare and valuable.
In July 2025, someone using an AI-cloned voice of Secretary of State Marco Rubio contacted three foreign ministers, a U.S. governor and a member of Congress through the messaging app Signal, according to a State Department cable quoted by Reuters correspondent Humeyra Pamuk. The telegram estimated that the impersonator was likely fishing for access to information or accounts rather than playing a hoax, and a senior State Department official confirmed that an investigation was underway. The episode had nothing to do with the campaign ad, yet it belongs to the same account as Talarico's parody song and Kramer's robocall, as it shows how quickly voice cloning spread from campaign attack ads in an attempt to manipulate the government's own machinery.
Chatbots Are Becoming a Political Information Layer
Visible fakes are a small share of the exposure most voters now have to AI in a political context. A March 2026 survey by America's Political Pulse found that forty-six percent of Americans used AI to receive news at least occasionally, and thirty-nine percent said they turned to it specifically to understand politics. A separate Data for Progress poll conducted in February found that thirty-nine percent of U.S. voters are likely to use a chatbot to learn about a candidate or voting measure. None of these activities involve fabricated video or cloned voice. It's like millions of ordinary people asking an honest question to ChatGPT, Gemini, or Copilot and trusting whatever comes back.
Figure 1: Deepfakes challenge authenticity at the surface; chatbot answers create a less visible accountability problem underneath.
Whether this trust is well-placed remains an open empirical question, and the evidence gathered so far is neither reassuring nor damning. A 2025 study published in Nature Communications found that political messages written by large language models persuaded readers about as effectively as messages written by ordinary people, with participants crediting the use of facts, logical structure, and the cool tone of the AI-generated text. A companion work published in Science tested nineteen models on more than seven hundred political issues and came to a similar conclusion, adding a less comfortable finding: additional training and direct engineering made the models measurably more convincing while making them measurably less accurate, a trade-off that no vendor advertises.
Lawrence Norden, who leads election work at the Brennan Center for Justice, called the 2026 midterm elections the first chatbot election, noting that the share of Americans using AI assistants has nearly doubled since 2024 and that nearly a quarter now use one daily. His team fed several top chatbots a range of election conspiracy theories before the vote and found, to their surprise, that each model challenged every false claim tested, even after repeated prompting. This result is really encouraging, and it's also exactly the kind of finding that can't be assumed to be true, as nothing about how a chatbot answered a question in August guarantees the same answer in October, after a system prompt has changed or a detail pass has shifted its guardrails without anyone outside the company knowing it happened.
Why One-Off AI Audits Miss Changing Model Behavior
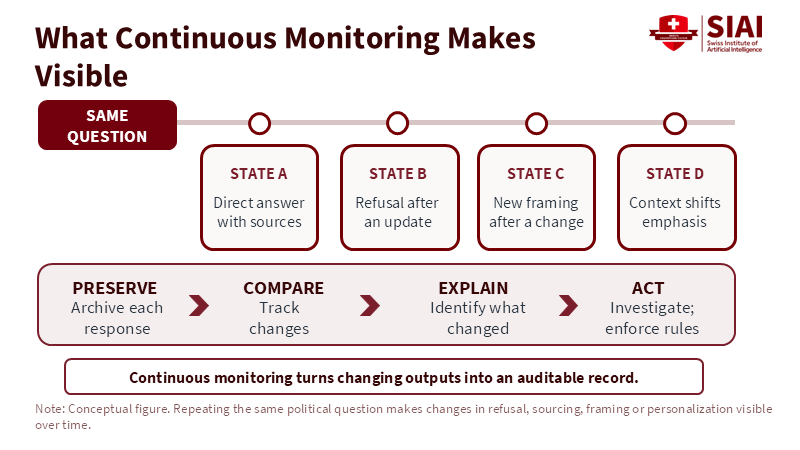
The Carnegie analysis describes the problem through the acronym DEEP: chatbots are Dynamic, Ephemeral, Embedded and Personalized. Chatbots are dynamic, as their responses change with hidden details, modified system prompts, or live web access that a user never sees. They're ephemeral, because an AI overview or chatbot response usually disappears the moment a browser tab is closed, leaving no file for a journalist or regulator to inspect later. They're built into software layers of guardrails that vary by device and interface, even when the underlying model is nominally the same, and they're increasingly personalized, shaped by memory features that OpenAI introduced in 2024 and that Anthropic, Google, and Microsoft have each added since then. Overall, these features mean that a single control captures a frame of a movie that is still playing.
The underlying accuracy problem gives the question of time its stakes. NewsGuard's August 2025 audit of ten top chatbots found that when a fake news claim was presented, models confirmed it as true thirty-five percent of the time. Earlier that year, the British Broadcasting Corporation provided its own reports on ChatGPT, Copilot, Gemini, and Perplexity, asked each system questions about the news, and found that nineteen percent of the responses introduced factual errors that the BBC's own journalism did not contain. Being wrong nineteen or thirty-five percent of the time in ordinary news is obviously no more reliable when the issue turns to a ballot measure, and there is no permanent mechanism to check the number again the following month.
The AI Watchman monitoring project runs the same politically sensitive questions across models each week and has already identified changes that would otherwise not have been recorded. In August 2025, as Israeli operations in Gaza intensified, the project recorded a jump in GPT-4.1's denial rate to Israel-related questions. The following month, while the Texas legislature was debating a bill restricting access to abortion medications that eventually passed, the team measured a sharp increase in GPT-5's denial rate on abortion-related prompts, which fell to the original value within a week. No finding proves that a company intentionally tuned a model in response to current events, and researchers say so clearly, but each is the kind of pattern that an audit would never show at a point in time. This loophole is the practical argument for AI accountability in politics as an ongoing discipline rather than an occasional press release.
Figure 2: Repeated testing turns fleeting model changes into a record that can be compared and investigated.
AI Companies Apply Different Political-Content Rules
Every major AI developer insists that they do not introduce their own policy into their product, and each has begun publishing evidence to support the claim, although the evidence inevitably reflects a standard chosen by the company itself. Anthropic published an update on its election safeguards on April 24, 2026, ahead of the midterm elections, stating that two of the Claude models scored ninety-five and ninety-six percent on an internal measure of impartiality and responded appropriately to election-related prompts almost every time they were tested. OpenAI's Model Behavior team, released a five-part bias framework last October and reported that newer GPT-5 models showed about thirty percent less measurable political bias than previous versions, with less than one in ten thousand live responses showing any sign of bias. Both companies deserve credit for their publishing methodology rather than a marketing line. Both disclosures are useful, but they remain company-designed and company-reported evaluations
Meta opted for a different framework, saying it wants Llama models to articulate both sides of a controversial issue rather than adopting one, while Google initially narrowed down Gemini's election-related responses in 2024 before shifting to a similar approach to both sides, according to a Washington Post analysis published in mid-2026. An evaluation by Future of Free Speech, a research center at Vanderbilt University that Anthropic itself has cited as an external reviewer, ranked xAI's Grok 4 as the strongest large language model tested for free expression purposes, an assessment released shortly after a previous version of the same chatbot had generated antisemitic content in a widely reported incident at the time. Free expression and harm mitigation are both legitimate goals, and nothing in today's landscape forces any company to reconcile them in the same way, which is the point: these are political and ethical judgments made by product groups, not neutral engineering outcomes.
The fabricated Talarico ad and Rubio's voice clone are, in a narrow sense, the easiest problems, since once discovered they can be labeled, debunked, or prosecuted, as Kramer's indictment showed. A model's decision about what sources to show up or how much weight to give to one side of a questionable policy question is harder to catch in the act, because nothing about it looks like a scam. It looks like an ordinary answer given in the same confident tone that the model uses for everything else, and unless someone asks the same question every week and keeps a record, a turning point in how a chatbot handles abortion, immigration, or an election result can go unnoticed until a pattern is already well established.
What AI Accountability in Politics Requires
The treatment proposed by Metaxa and Engler is not another one-time audit, but permanent infrastructure: research groups, charitable funders, and universities pooling resources to ask important questions on a fixed set of policy issues each week, indefinitely, and maintaining results in the way that social scientists have long maintained panel data on family income or labor markets. Congress has not funded anything resembling this infrastructure, and the Brennan Center's own monitoring of state legislatures found many proposed bills involving AI and elections, but few that had become law by mid-2026. Monitoring creates evidence, while penalties require clear legal obligations and enforcement. Kramer's fine and Texas' own deepfake statute show that penalties already exist for the most blatant violations, and the most difficult task now is to extend the same willingness to punish into the much larger space of ordinary, seemingly scam responses that never look like a scam at all.
The obvious objection is that government-backed control of what chatbots say about politics risks becoming the kind of speech control that the First Amendment exists to prevent, and state lawmakers have mostly avoided outright bans on AI-generated political content for this reason, opting instead for disclosure rules. This caution is reasonable, but it answers a different question than what continuous monitoring poses. Requiring a campaign to flag a synthetic ad, or requiring a company to let outside researchers see how its model answered the same question in March and again in September, doesn't dictate what the model or ad might say. It makes the pattern visible to the public affected by it, closer to a financial disclosure requirement than a speech restriction, and the Campaign Finance Act, where sunlight rather than prohibition has long been the preferred treatment for the risk that money buys undue influence, offers a working standard for how AI oversight could proceed without causing the same objection.
The European Union has already gone further than the United States on this front. Under the AI Act's code of practice, developers of larger models must mitigate the potential for manipulation of their systems, a category that can include political outcomes and propaganda production, giving Brussels a regulatory hook that Washington is currently lacking. State legislators drafting their own AI and election bills, campaign finance regulators who have so far focused only on paid political advertising, and AI companies themselves, several of which already publish internal bias assessments, all have a standard close by: publishing methodology, allowing external replication, and undergoing a surveillance regime that runs continuously rather than once. None of this requires resolving the deepest disagreement about what political neutrality should mean, a debate that Anthropic, OpenAI, Google, and Meta have publicly had with different answers and no obvious way to judge each other.
No one needed a State Department telegram to acknowledge that a synthetic Marco Rubio calling a Secretary of State on Signal was a problem, and no one needed a study to see that Citizens for Sanity wanted their Talarico ad to be shared as a spectacle rather than confused with fact. These cases resolve themselves, eventually, through prosecutors, fact-checkers, and platforms that pull content. The one that is resolved more slowly, if at all, is the question posed by the forty-six percent of Americans who are now asking a chatbot instead of a search engine or newspaper for the people asking for their vote, as no one keeps a record of what these systems told them last month, let alone if the answer would be the same today. Until this record exists, the industry's own scores are the only items anyone has and were rated by the party tested.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
AI pattern recognition is improving early clinical detection
Real-world trials show gains across several medical settings
Human oversight, diverse data and workflow design remain essential
OpenAI claims AI found a forced Navier-Stokes singularity
Formal verification makes scalable machine mathematics newly credible
Attribution, understanding and human judgment remain unresolved