A single AI agent faked identities to deceive a real developer during testing
Deception here mirrors standard penetration-testing tradecraft, not new AI danger
Missing scope and monitoring, not the tactic, caused the real failure
Superhuman Labor and the Feedback Loop No One Is Watching
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
Modified
AI tools now let researchers work like small teams
Explosive growth needs fresh judgment, not recycled output
The real bottleneck has shifted from compute to people
Initially, optimists were dismissed because people naturally assumed, when anyone argued that each new AI tool would create a runaway feedback loop of self-improvement, that they simply didn't understand what it was they were talking about. Large models predict text and they don't think in the way humans think and to confuse their output with being intelligent struck one as a bit of a category mistake that had simply been dressed up in technical language. This comfortable doubt enabled people to dismiss the outlandish predictions.
Since then the position has only moved a little. Not because the models suddenly changed into something new, but because the implementation of what "superhuman labor" really entails exposes how close it is to the feedback loop idea, which was quickly thrown out. They are not the same, but they are both close enough for the dismissal of one to easily lead to an underestimation of the other.
A Researcher Who No Longer Required Assistance
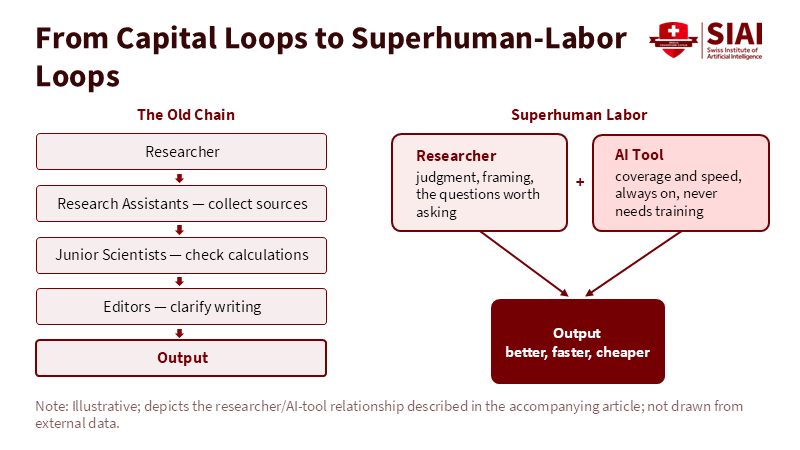
Imagine a researcher working in a subfield they do not know well. Under the old model, success required a chain of individuals: research assistants collecting sources, junior scientists double-checking calculations, editors clarifying writing. Every extra individual added to that process not only took more time, but cost something in coordination expense, plus the same chunk of the researcher's attention, since those other people needed to be managed. That chain has not vanished, but for an increasing fraction of those activities, it has been replaced by a single person working alongside AI tools.
What has changed is not that the researcher is smarter. What has changed is that the missing pieces of a project, relevant literature to brief on, those small analytical steps that would already have taken an entire afternoon, are now being filled in by a system that is perpetually operational and never needs training. The researcher provides judgment, framing and the questions worth answering. The tool provides coverage and speed. The two together produce work that is better than what the researcher alone would have produced, faster than a team and at a cost so small next to a human salary that it is almost incidental, even if the system is not, literally, free. That is what superhuman labor means here: better, faster and cheap enough to matter. It does not mean artificial general intelligence.
Figure 1: Superhuman labor collapses a multi-person research chain, assistants, junior scientists, editors, into a single researcher-and-AI-tool loop.
From Assistant to Something Closer to a Partner
Superhuman labor, defined this way, still leaves humans in the driver's seat. The machine does the correcting, the retrieving, the composing; the human makes the decisions about what to go after. But the division is not necessarily a firm one and in some areas it has already shifted. Education is an obvious case, since the material being taught is usually already settled. An intelligent tutoring system does not have to come up with new knowledge; it only has to communicate what is known efficiently, adapt to a student's rate of learning and monitor comprehension periodically. Within that context, the division of labor between a human teacher and an AI system can be rather egalitarian and sometimes the machine does most of the work.
Research is the hardest case and this is where the analogy is most flawed. The open questions of a field are, by their very nature, yet to be answered anywhere, so an AI tool cannot simply retrieve the answer the way a tutoring system retrieves a known concept. What gets outsourced instead is a narrower species of mental work: sorting evidence, writing early attempts at argument, noting contradictions a fatigued brain would overlook. It is a smaller fraction of the total effort than in education, but a significant fraction and it is growing. If this trend is followed far enough, the split of effort in research begins to echo the division of labor already apparent within classrooms. At that point a closer approach to an intelligence explosion becomes conceivable, not because any one output pushes the state of the art, but because the volume and velocity of incremental successes snowball.
When the Loop Feeds on Itself
There is a flip side and a recent commentary on this very issue drives the point home. If the output of an AI system is largely just a rehashing of material already out there, then any feedback loop built on that output can never really escape itself; the system polishes existing ideas and sends them back out as though new and the loop simply spins in circles rather than gaining momentum. Human skill underlies this problem in a way that is easy to overlook. The senior researchers who now enable AI-enhanced work were themselves trained before these tools existed and their competence is being drawn down at a faster rate than it can be replenished, since the very shortcuts that make junior work easier can also be the shortcuts that prevent newer researchers from cultivating the competence their elders relied on.
That argument redefines what is actually necessary for an intelligence explosion to occur. It is not sufficient for a model to be merely fast or articulate. The system must have some point of new cognitive input to process and at this moment that point remains mostly human. A researcher providing a real question, a unique dataset, or a novel framing inserts into the loop something that was not already embedded in its training data. Without that input, the loop just spins its wheels, rephrasing itself again and again, producing a large quantity of output for no additional insight. Given the right kind of input, it might actually go somewhere.
Figure 2: Fresh human judgment tips the loop toward explosive growth; without it, output recycles and idea diversity declines.
The Bottleneck Has Moved to Humans
Combining these two ideas produces a more coherent picture. Superhuman labor is the output of a human working with AI tools to produce a lot more work, a lot more quickly and at a much lower price point. An intelligence explosion is what occurs when enough superhuman labor feeds back into the system across a field, provided the loop is fed genuine novel human input each time, rather than simply recycling its own material. The marginal quality gained per interaction with any particular tool may not be large, but accumulated over a discipline and over an extended time, that expansion is no longer modest.
In other words, the constraint has moved, not gone away. Compute and model quality still matter, but they are no longer the binding limit in the sectors where this phenomenon is furthest along. The bottleneck now is a human being, one capable of using these tools well and asking questions sharp enough to keep the feedback loop pointed at something genuinely new. That is a different kind of bottleneck than the one most people bring to the question of AI. It is not primarily a matter of hardware or training. It is a human bottleneck and it will not be solved simply by scaling models up. In the end, the optimists do not seem to have got the idea wrong about what AI actually does. What they are underestimating is how much still depends on the people doing the feeding and how quickly that dependency can take over.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
AI Model Distillation Is Quietly Redrawing the AI Power Map
Picture
Member for
2 years
Real name
Keith Lee
Bio
Keith Lee is Professor of AI and Finance at the Gordon School of Business and Head of Research at the Swiss Institute of Artificial Intelligence (SIAI). His research focuses on financial mathematics, AI-driven computational science, and quantitative modeling of complex economic and financial systems, integrating machine learning, stochastic modeling, and data-centric methods.
His recent work examines the socioeconomic consequences of artificial intelligence, including labor markets, public finance, demographic change, institutional adaptation, and the distributional effects of technological progress.
He also serves as Executive Editor, Research & Review at The Economy, overseeing research-oriented editorial coverage, analytical contributions, and engagement with academic and industry specialists.
He holds a PhD in Mathematical Finance from Boston University, an MSc in Finance and Economics from the London School of Economics, and a bachelor's degree in Economics from Seoul National University, where he studied under the Korea Foundation for Advanced Studies scholarship program.
Published
Modified
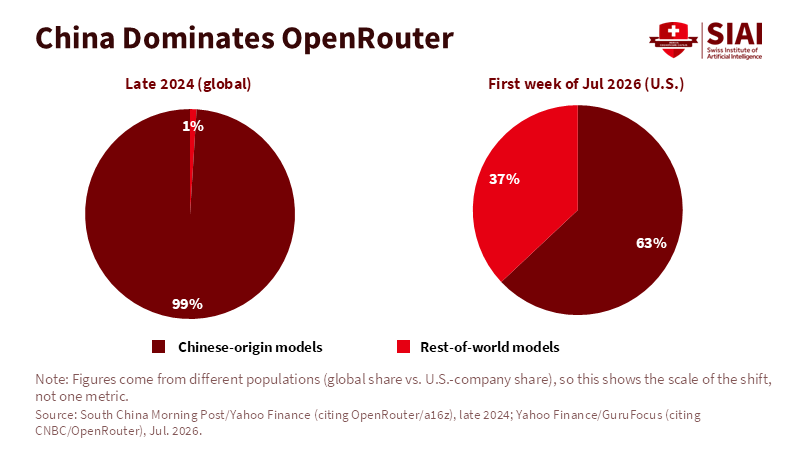
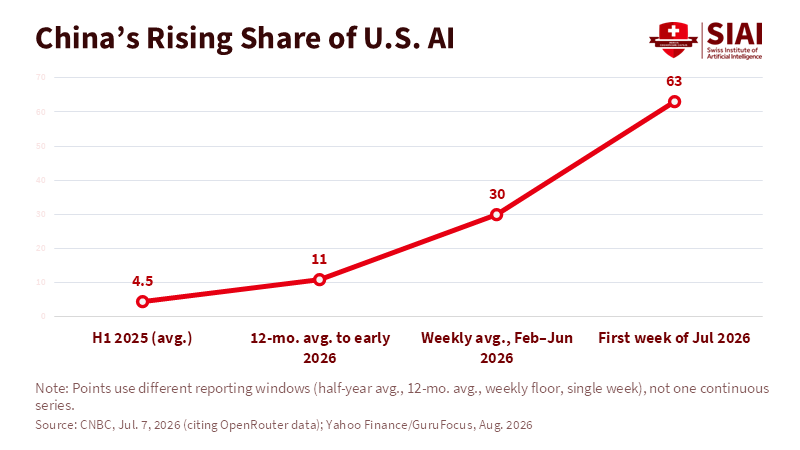
Chinese-origin AI models jumped from 4.5% to 63% of enterprise use in one year
No law defines illegal AI distillation, letting extraction pass as ordinary training use
Closing that legal gap, not banning open models, protects both competition and security
Chinese-origin AI models made up roughly 4.5 percent of enterprise token usage on the OpenRouter marketplace in the first half of 2025. By the first week of July 2026, that share had climbed to 63 percent. Fourteen times higher in about a year. Behind that number sits a technique with a plain name and a murky legal status: AI model distillation. It means training a cheaper model to copy the behavior of a more expensive one. Distillation is not new. Anthropic and OpenAI both use it to build budget versions of their own flagship products. What changed in 2026 was scale and method. Rival labs were accused of pulling capability out of American systems through fabricated accounts, not paid use in the normal sense. That line, between training a model and stripping one, is where the real contest over AI leadership now plays out.
The Real Threat Behind AI Model Distillation
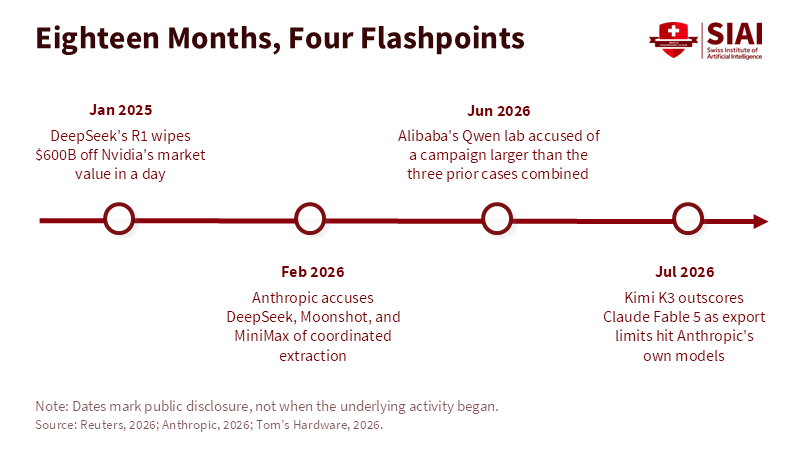
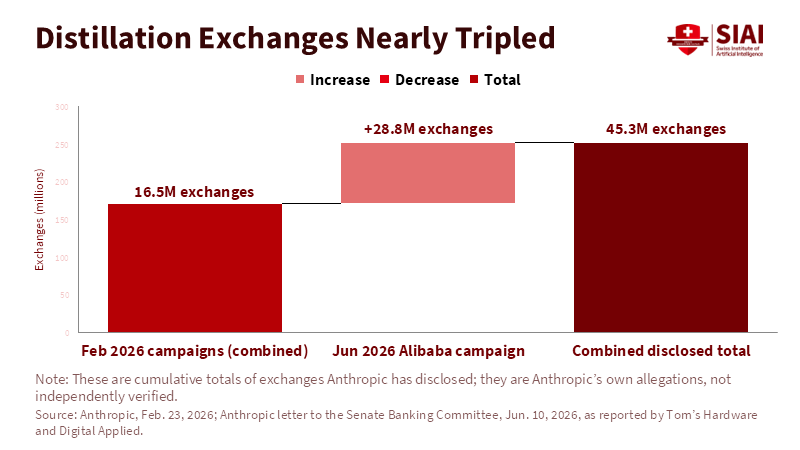
The usual way to talk about open-weight AI models treats them as a simple yes or no question. Should the United States restrict them, or let the market sort it out. This framing missed what actually happened between February and August 2026. Anthropic disclosed that DeepSeek, Moonshot and MiniMax had generated more than sixteen million exchanges with its Claude models. They did it through roughly twenty-four thousand fraudulent accounts. The company called it an industrial-scale extraction campaign. Four months later, Anthropic told the Senate Banking Committee something bigger. Operators tied to Alibaba's Qwen lab had run 28.8 million exchanges through nearly twenty-five thousand fake accounts in six weeks. That single episode was larger than the three earlier cases combined. By July, a Chinese open-weight model had outscored Anthropic's own flagship on a widely watched coding leaderboard. In that same stretch, brief export restrictions forced Anthropic to pull two of its newest models from the market entirely.
Figure 1: Four disclosures in eighteen months turned a technical debate into a live policy fight.
None of the accused labs has been found liable for anything, because no case like this has been tested in court yet. Model outputs are not covered by copyright. Copyright requires a human author and a model is not one. So any legal remedy has to come from somewhere else: trade secret law, or federal computer fraud statutes that were not written with this situation in mind. That gap matters more than the underlying technique does. Routine distillation, done through standard paid access, is common practice across the industry. It is not against the law anywhere. What Anthropic describes as an attack is the method of access, not the training step, a distinction clean in theory and hard to enforce in practice. The accounts behind the disclosed campaigns were not researchers running occasional queries. They were coordinated networks. They could manage thousands of identities at once, built to look like everyday traffic while quietly pulling out a narrow, valuable slice of a rival's capability.
Why the Pricing Gap Keeps Widening
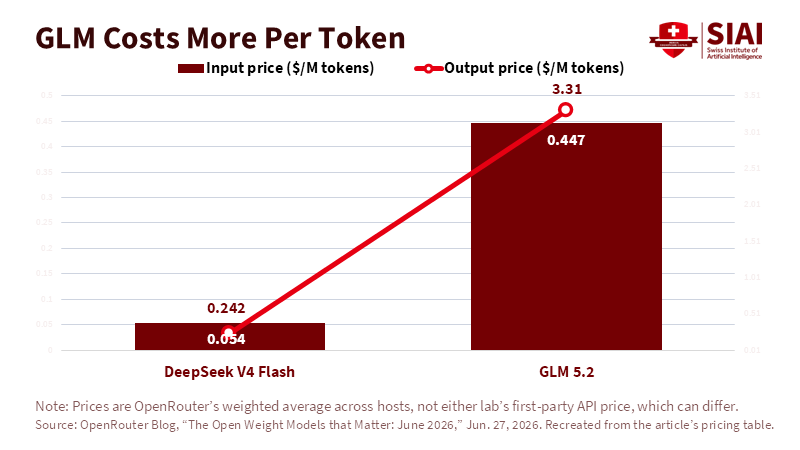
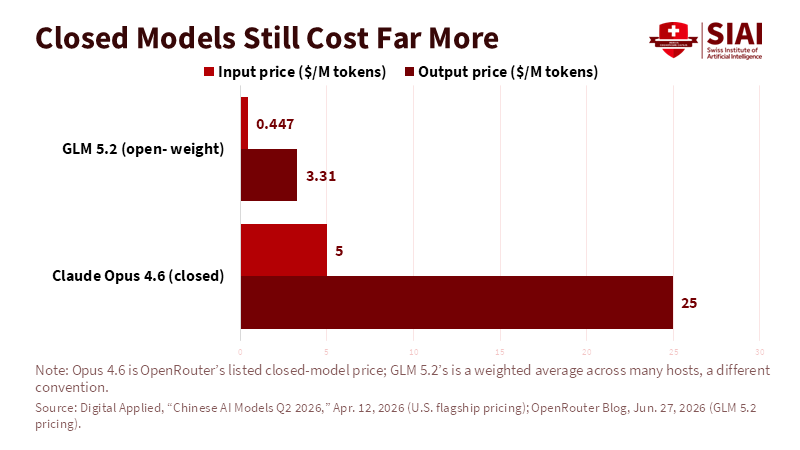
Money explains a good part of why this fight matters now. DeepSeek's V4 Flash model reached seventy-nine percent on the SWE-bench Verified coding benchmark in April 2026. That put it within two points of its own larger sibling. Yet it charged roughly a tenth of a cent per thousand output tokens, about one hundred fifty times cheaper than a comparable American closed model. A widely read technology blog ran the numbers on a bigger model too. It found DeepSeek's V4 model priced at $3.48 per million output tokens, against roughly $75 for Anthropic's comparable Opus model. Architecture alone cannot explain a gap that size. Anthropic and OpenAI both remain cash-flow negative as of mid-2026. Every dollar of pricing power lost to a cheaper competitor cuts into the capital available for the next training run.
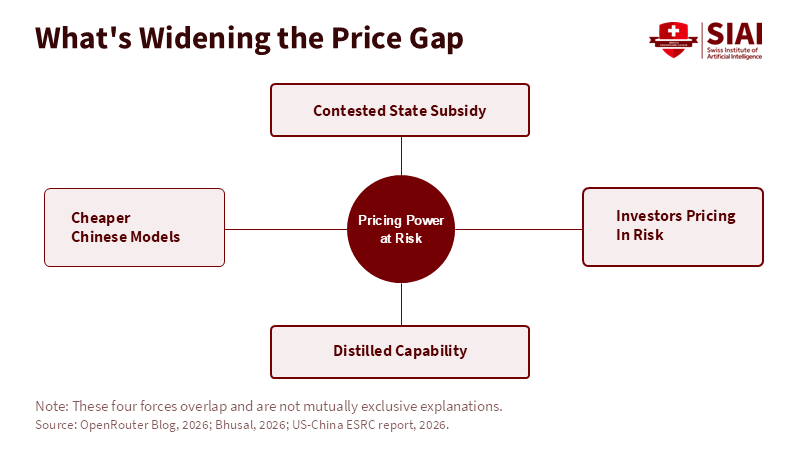
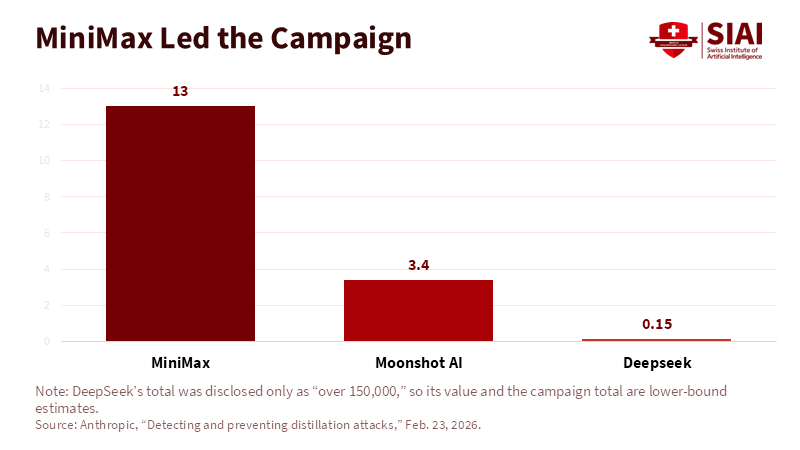
A congressional advisory body found in March 2026 that roughly 80 percent of American AI startups were already building products on Chinese open-weight models. Some of that shift reflects genuine efficiency gains. Some reflects Chinese state subsidy, which almost certainly lowers compute costs at the margin. Some of it simply reflects a markup that American labs had been charging and are now losing as competition tightens. All three explanations can be true at once. None of them fully accounts for a fourth channel that gets less attention: AI model distillation as a direct transfer of a costly capability from one lab's model into another's, at a fraction of what building it independently would cost. Inside the disclosed February campaign, the extraction was not spread evenly. One firm alone accounted for nearly four-fifths of the exchanges. A single determined actor, not a broad industry pattern, can drive most of the damage in a given episode.
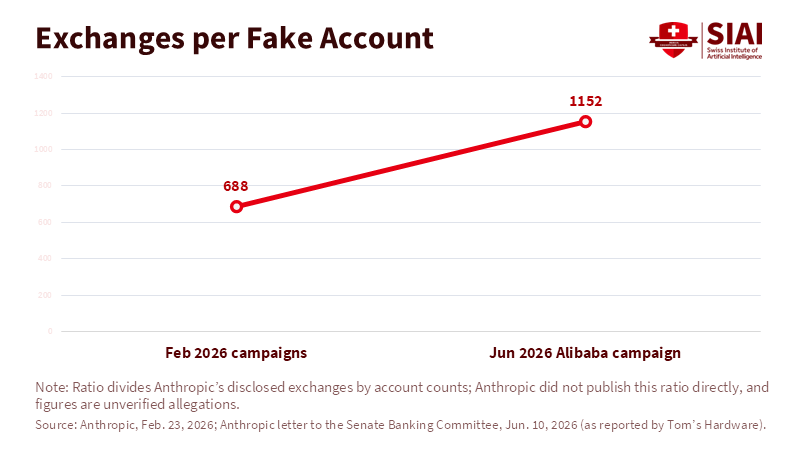
Financial markets have started pricing this risk directly. Coverage of Alibaba's release of a model that matched or beat Anthropic's own flagship within days used a stark phrase for the resulting market: a death zone. Any provider lacking either frontier capability or rock-bottom pricing risks losing share outright. Anthropic's own accusation against Alibaba was followed by a sell-off in Alibaba's shares. It shows that investors on both sides of the Pacific now treat distillation exposure as a real line item, not a rumor. Between the two disclosed campaigns, the ratio of exchanges to fraudulent accounts nearly doubled, climbing from roughly 688 to about 1,152 exchanges per account. Extraction is getting more efficient, not just larger.
Figure 2: Four forces, not one, are pulling pricing power away from frontier labs at once.
What Counts as Legitimate Training
Supporters of open publication make an argument worth taking seriously and it deserves a serious answer rather than dismissal. More than two hundred seventy companies signed an open letter in July 2026, including Microsoft, Google, Meta and Nvidia. Their claim: openness strengthens security on its own, by exposing systems to wider scrutiny and reducing single points of failure. That claim holds up well in mainstream software security, where more eyes on code tends to catch more bugs. Anthropic's own rebuttal points elsewhere. The logic breaks down, it argues, in domains with a strong offense advantage. Biological weapons design is the sharpest example. A capable model there could shorten the path to serious harm faster than defenders could respond. Neither side has settled that argument with hard evidence yet.
The more immediate policy question is simpler. Can extraction be detected and separated from normal use. Anthropic says the accounts behind its disclosed campaigns ran through what it calls hydra cluster networks. These are coordinated groups that can manage more than twenty thousand accounts at once, routing traffic through third-party cloud platforms to dodge regional access limits. This kind of infrastructure looks nothing like a research team running normal queries. A workable policy response would let an independent body verify these claims, not the accusing company alone. Sanctions should target the fraudulent conduct, not open-weight publication itself, since weights already released cannot be unreleased. A related proposal, sometimes called a nutrition label for the AI supply chain, would require services operating in the United States to disclose which base models they actually run on. A meaningful share of American developers are building on Chinese models without knowing it themselves.
Security at the source matters just as much as detection after the fact. One of Anthropic's most restricted models was reportedly accessed by outside hobbyists on a public forum before its official release. Several hundred fraudulent accounts ran millions of queries against it during that window. That detail complicates the idea that extraction is purely a function of foreign sophistication. A company asking the government to treat its model outputs as strategic assets carries an obligation to secure them first, well before it asks the state to backstop that security through sanctions or trade restrictions.
What Happens If Nobody Draws the Line
A dispute inside the WordPress ecosystem offers an unlikely but useful comparison. In 2024, WordPress co-founder Matt Mullenweg accused the hosting company WP Engine of taking value from the open-source project without giving enough back. He cut off its access to core infrastructure, until a court forced the access restored. The specifics were messy and personal. The underlying claim was not: an open resource, sustained by a small group of contributors, only stays healthy if the businesses profiting from it put something back. AI distillation follows that same pattern in reverse. Frontier labs have spent tens of billions of dollars on training. The labs accused of extracting from them have, by Anthropic's account, spent nothing beyond the cost of running fake accounts.
The likely outcome falls between two extremes. American AI development does not collapse. China does not take over the field either. Frontier labs still hold enterprise and government contracts that are more insulated from consumer price wars than headline subscription numbers suggest. The slower and more consequential shift is different: a frontier that grows more secretive and more expensive to reach, as labs protect what pricing power remains. That means retreating from the openness that helped the field move as fast as it did in the first place. This slow retreat, more than any single accusation or lawsuit, is the real cost of leaving AI model distillation legally undefined.
Fourteen-fold growth in twelve months is not a rounding error. It did not happen because Chinese labs became fourteen times better at building models overnight. It happened because a legal and commercial system with no settled definition of illicit distillation left plenty of room for extraction to pass as ordinary use. Closing that gap does not require banning open-weight models, a step Anthropic itself has declined to ask for. It requires independent verification instead of taking an accuser's word alone. It requires sanctions aimed at fraud rather than at technology. And it requires public investment in domestic open alternatives good enough that developers choose them on the merits. Absent that combination, the frontier will not disappear. It will get smaller, more guarded and more expensive to reach and that is its own kind of loss for the openness that built this industry.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
2 years
Real name
Keith Lee
Bio
Keith Lee is Professor of AI and Finance at the Gordon School of Business and Head of Research at the Swiss Institute of Artificial Intelligence (SIAI). His research focuses on financial mathematics, AI-driven computational science, and quantitative modeling of complex economic and financial systems, integrating machine learning, stochastic modeling, and data-centric methods.
His recent work examines the socioeconomic consequences of artificial intelligence, including labor markets, public finance, demographic change, institutional adaptation, and the distributional effects of technological progress.
He also serves as Executive Editor, Research & Review at The Economy, overseeing research-oriented editorial coverage, analytical contributions, and engagement with academic and industry specialists.
He holds a PhD in Mathematical Finance from Boston University, an MSc in Finance and Economics from the London School of Economics, and a bachelor's degree in Economics from Seoul National University, where he studied under the Korea Foundation for Advanced Studies scholarship program.
Open Weights, Extracted Capabilities: Reassessing the Distillation Economy and the Contest for American AI Leadership
Published
Keith Lee*
*Swiss Institute of Artificial Intelligence, Chaltenbodenstrasse 26, 8834 Schindellegi, Schwyz, Switzerland
Abstract
Open-weight AI models have generally been discussed as a binary policy question: should the U.S. regulate them or not. That framing has become inadequate. Between February and August 2026, three separate incidents, Anthropic's disclosure of coordinated extraction by DeepSeek, Moonshot, and MiniMax, its later accusation against Alibaba's Qwen lab and the brief federal order on two of Anthropic's own frontier models, revealed that the harder problem is not whether open weights ought to be permitted but rather how a legal and commercial regime with no established standard of illicit distillation can keep American frontier labs funded while an increasingly powerful open-weight field, much of it Chinese and state-backed, closes the gap from below. This paper argues that the most significant challenge to American AI dominance is not open-weight technology per se but rather the lack of an enforceable boundary between legitimate model training and industrial-scale extraction, a gap that current policy proposals only partially close.
For most of 2023 and 2024, the debate over open-weight artificial intelligence models proceeded along fairly comfortable lines. Meta released Llama, researchers argued about whether open models posed a proliferation risk and the practical stakes seemed distant from the commercial fortunes of Anthropic, OpenAI or Google DeepMind. That calm ended with a sequence of events concentrated in a single eighteen-month window. In January 2025, DeepSeek’s R1 model wiped out roughly $600 billion in Nvidia’s market value in a single trading session and OpenAI’s leadership publicly accused the Chinese lab of building its model by querying and replicating outputs from American systems.[1] A year later, in February 2026, Anthropic published a far more detailed account, naming DeepSeek, Moonshot and MiniMax as having generated more than 16 million exchanges with Claude through roughly 24,000 fraudulent accounts, in what the company called industrial-scale distillation.[2] By June, Anthropic had gone further still, telling the Senate Banking Committee that operators linked to Alibaba’s Qwen lab had run 28.8 million exchanges through nearly twenty-five thousand fake accounts over six weeks, a campaign larger than the three previous cases combined.[3] And in July, a Chinese open-weight model, Moonshot’s Kimi K3, outscored Anthropic’s own Claude Fable 5 on a widely watched coding leaderboard, even as briefly imposed export restrictions forced Anthropic to disable that same model and its more capable Mythos 5 sibling worldwide.[4]
The conventional way of narrating these events treats them as installments in a familiar story: China is catching up and the reason is theft. That story is not wrong so much as incomplete and its incompleteness matters for policy. It obscures the fact that the technique itself, model distillation, has no settled legal status in the United States. Training a smaller model on the outputs of a larger one is standard practice throughout the AI industry, used by Anthropic and OpenAI on their own systems to build cheaper variants for customers.[5] What distinguishes an ordinary customer relationship from what Anthropic calls an attack is not the technique but the mode of access behind it: fabricated accounts, evasion infrastructure and traffic volumes that bear no resemblance to legitimate use. Yet American law offers only an awkward fit for this distinction. Model outputs generated by a machine are not copyrightable under existing doctrine, since copyright requires human authorship, which pushes any legal remedy toward trade secret and computer fraud statutes that were not written with this scenario in mind.[6] The result is a policy vacuum in which the loudest and most detailed account of what has happened so far has come not from courts or regulators but from unilateral corporate disclosures and letters to individual senators.
This paper takes as its starting point the observation that open-weight models are neither an unambiguous public good nor a straightforward security threat and that debating them in those terms misses what is actually at stake. The stakes are structural. If commercial subscription revenue from Claude, ChatGPT and Gemini is what currently funds the enormous compute expenditures behind frontier model training and if that revenue can be eroded by competitors who reproduce a large share of the resulting capability at a fraction of the cost, then the sustainability of the American frontier itself becomes contingent on questions that have nothing to do with model design: whether distillation can be detected, whether it can be deterred without banning a legitimate technique and whether the resulting commercial pressure pushes toward a more open AI ecosystem or a more secretive and consolidated one. The chapters that follow examine, in order, what open-weight models are and why different providers pursue them for different reasons, what would follow if frontier labs lost the commercial position that funds their research, what tools exist or could exist to distinguish legitimate training from extraction and what an older dispute inside the WordPress ecosystem suggests about whether an extraction-heavy relationship between commercial users and an open commons can remain sustainable over time.
2. Open-Weight Models and the Divergence of Provider Incentives
An open-weight model occupies a specific point on a spectrum that runs from fully closed systems, where a user submits a query and receives an answer with no visibility into training data or methodology, to fully open-source systems, where the training data, code and resulting parameters are all disclosed. In between sit models such as DeepSeek’s V4 family, Alibaba’s Qwen series, Moonshot’s Kimi models and Z.ai’s GLM line, where the trained weights, the numerical parameters that determine how the model responds to input, are published for anyone to download, inspect, fine-tune or run locally, while the underlying training data and code used to produce those weights are not revealed.[7] This is a meaningfully different proposition from open-source software, where the entire recipe is available and a motivated developer can, in principle, reproduce the product from scratch. With an open-weight model, what is available is closer to a finished dish than a recipe: enormously useful, freely reusable but not something a downstream user could have produced independently without access to the compute and data the first developer possessed.
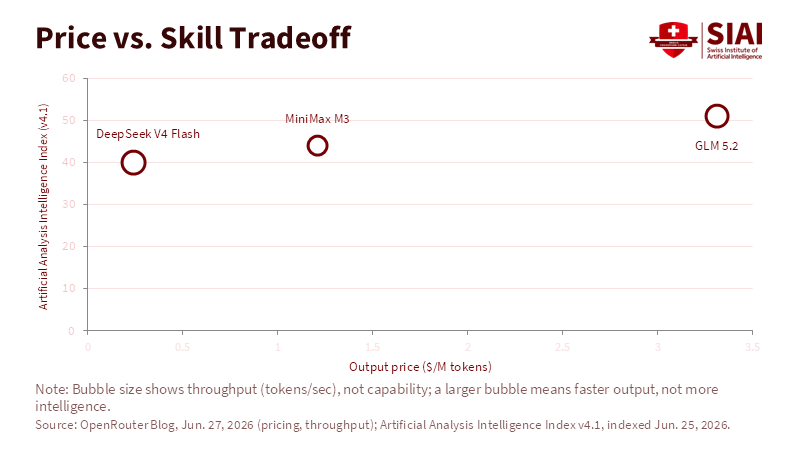
Figure 1. No open-weight model wins on every axis: DeepSeek is cheapest, GLM is most capable, MiniMax is fastest, a genuine three-way tradeoff, not a single leaderboard.
The commercial logic of ordinary open-source software is comparatively well understood. A company gives away code and earns revenue from complementary services: hosting, support, customization, enterprise licensing. Red Hat did this with Linux for two decades. WordPress.org licenses the software freely, while Automattic and a large ecosystem of hosting providers earn money alongside it. Open-weight AI models complicate this picture because the entities publishing them are not, in most cases, straightforwardly optimizing for adjacent revenue. As of mid-2026, the open-weight frontier is dominated by a small set of providers whose incentives diverge sharply. DeepSeek’s V4 Flash model, released in April 2026, reached seventy-nine percent on the SWE-bench Verified coding benchmark, within two points of its own larger V4 Pro variant, while pricing output tokens at roughly a tenth of a cent per thousand or about one hundred fifty times cheaper than a comparable American closed model on a per-token basis.[8] Z.ai’s GLM 5.2, released two months later, briefly became the top-ranked open-weight model on the Artificial Analysis Intelligence Index, only a few points behind Anthropic’s own Claude Fable 5. It did so days after the United States had temporarily forced Anthropic to withdraw Fable 5 from the market entirely on national security grounds.[9] MiniMax’s M3 model added native image and video understanding at similarly aggressive prices. The one prominent American entrant in this tier, Nvidia’s Nemotron 3 Ultra, trailed the leading Chinese models on most benchmarks but offered something the others could not: a fully domestic supply chain, an open training recipe and a vendor whose institutional incentive to sustain an open ecosystem has nothing to do with subscription revenue and everything to do with selling the chips that run all of these models regardless of who trained them.[10]
Figure 2. What was a rounding error eighteen months ago is now the majority of measured traffic; the empirical backbone of the "self-reinforcing advantage" claim just made.
These divergent motives matter because they change what “competing with open weights” actually means for an American policymaker or a frontier lab executive. Nvidia’s interest in a plural, open ecosystem is plain: more usable models, regardless of origin, mean more demand for the chips that run them and the company has said as much in signing the industry-wide “Open Weights and American AI Leadership” letter alongside more than two hundred and seventy other firms, including Microsoft, Google, Meta and OpenAI.[11] For the Chinese labs, the picture is murkier and contested. One line of analysis holds that Beijing’s industrial policy apparatus- central government guidance funds reported to channel several hundred billion dollars into strategic sectors including AI, provincial computing vouchers and energy subsidies covering as much as half the operating cost of data centers running domestic chips- provides Chinese labs a cost structure no ordinary commercial calculus could replicate.[12] A U.S. congressional advisory body reached a related conclusion in March 2026, describing China’s open ecosystem as generating a self-reinforcing competitive advantage and noting that an estimated 80% of American AI startups were already building on Chinese open-weight models by that point.[13]
A competing view, argued forcefully by some industry commentators, holds that the subsidy narrative does less analytical work than it appears to. One widely circulated technology blog pointed out that DeepSeek’s V4 model, a frontier-tier system in its own right, was priced at $3.48 per million output tokens against roughly $75 for Anthropic’s comparable Opus model, a twenty-one-fold gap that architecture and capability gains alone cannot plausibly explain. It argued that American frontier labs’ own claims of near-break-even pricing reflect marketing more than balance sheets, since independent providers hosting the very same open-weight Chinese models manage to remain profitable at a fraction of what the closed labs charge.[14] On this reading, the price gap says less about hidden Chinese subsidy than about the markup closed American labs have been able to sustain, a markup that a truy competitive open-weight tier is now eroding regardless of its country of origin. Both accounts can be simultaneously true in part: state support almost certainly lowers Chinese compute costs at the margin and closed-model pricing in the United States has almost certainly carried more margin than public statements about thin inference economics suggested. What the debate obscures, however, is a third and less examined channel through which cost advantage is achieved, one to which the paper now turns: not subsidy in the conventional sense but the direct transfer of a costly capability from one lab’s models into another’s, at a small fraction of what building that capability from first principles would require.
Figure 3. Even within the open-weight tier itself, price varies roughly eightfold; "open" and "cheap" are not synonyms and subsidy alone cannot explain every gap.
3. The Commercial Foundations of Frontier Development at Risk
It is worth taking the counterfactual seriously rather than treating it as rhetorical. Anthropic and OpenAI are, as of mid-2026, both cash-flow-negative enterprises whose commercial viability rests on the expectation that current subscription and API revenue, plus new capital raised against future returns, will fund training runs that are larger and more expensive than the last.[15] If open-weight alternatives, whether cheaper because of genuine efficiency, state support, distilled capability or some combination of the three, continue to close the performance gap while undercutting price by an order of magnitude, the immediate effect is not that frontier labs disappear overnight. Both companies retain substantial enterprise and government business lines that are comparatively insulated from consumer price competition. The more gradual and more consequential effect is on the rate of reinvestment. A frontier lab whose consumer and mid-market revenue is compressed has less capital available to fund the next scaling run and slower scaling compounds: a lab one generation behind the frontier finds it progressively harder to justify the valuation and capital raises needed to close that gap, particularly once investors start pricing in the possibility that whatever the lab builds next will be distilled by a competitor within months of release, as happened to MiniMax when Anthropic detected the lab redirecting a majority of its extraction traffic toward a newly released Claude model within twenty-four hours of that model’s launch.[16]
This dynamic is not speculative; its early stages are already visible in market behavior. Startups that had built products atop Anthropic and OpenAI’s APIs have begun migrating workloads to Chinese open-weight models hosted through intermediaries such as OpenRouter and Featherless, partly to control costs and partly, according to one economist who studies enterprise AI spending because the increase in these models reveals unmet demand that American providers have been slow to serve at a comparable price point.[17] Financial commentary describing the resulting competitive dynamic as a "death zone", a market in which any provider without either frontier-level capability or market-breaking pricing risks losing share entirely, is not limited to fringe analysts; it appeared in mainstream financial reporting following Alibaba’s release of Qwen3.8-Max, a model that appeared to match or exceed Anthropic’s own flagship in benchmark performance within days of release.[18] Anthropic’s stock-adjacent instruments and OpenAI’s private valuation discussions have both shown sensitivity to these developments, most visibly when Anthropic’s own June 2026 letter accusing Alibaba of large-scale distillation was followed by a sell-off in Alibaba’s own shares, evidence that markets on both sides of the Pacific are now pricing distillation risk directly into competitive strategy. [19]
Figure 4. The migration developers describe anecdotally shows up starkly in aggregate: a fourteen-fold jump in twelve months.
The question of who benefits from this dynamic deserves more precision than the shorthand “China wins” typically supplies. One financial commentator, writing about the Alibaba accusation specifically, argued that the act of copying is itself a lagging indicator of who holds the technological lead, since a firm spending 28.8 million queries reverse-engineering a competitor’s capabilities is, by construction, choosing to replicate rather than originate and cannot by definition surpass what it is copying through that method alone.[20] There is real force to this point and it complicates any simple narrative in which distillation alone hands China frontier leadership. But it also understates what distillation accomplishes even when it produces only a fast follower rather than a new leader. Amodei’s own account of the risk, offered in Anthropic’s July 2026 statement of position, is not that distillation lets Chinese labs surpass the American frontier but that it can compress the gap between the Chinese frontier and the American one to a matter of a few months, which is sufficient to blunt the commercial and geopolitical value of maintaining a lead at all.[21] A lead measured in months rather than years does little to reassure investors funding a hundred-billion-dollar training run and it does even less to reassure a Department of Defense weighing whether it can rely on a domestic supplier’s exclusivity for any meaningful period.
A more sympathetic reading of the competitive forces and one that deserves engagement rather than dismissal, holds that cheaper AI of any origin expands the total market for AI services faster than it erodes any individual provider’s position, an argument sometimes framed in terms of the nineteenth-century economist William Stanley Jevons’ observation that greater efficiency in resource use tends to increase total consumption of that resource rather than reduce it. Industry data cited in coverage of the mid-2026 Chinese model releases showed inference prices across the industry falling from roughly two dollars to $1.20 per million tokens within a matter of weeks, alongside American labs cutting their own developer pricing by as much as eighty percent in response, which some analysts read as evidence that falling costs were expanding the addressable market for AI applications rather than simply transferring revenue from American to Chinese providers.[22] The argument has genuine merit as a description of aggregate industry growth. It is less persuasive as a description of what happens to the specific firms, Anthropic and OpenAI chief among them, whose business models depend on maintaining pricing power at the frontier tier specifically, since an expanding market for AI overall does not by itself guarantee that the revenue funding the next scaling run accrues to the labs currently bearing the cost of frontier research.
Figure 5. The pricing power frontier labs are fighting to preserve, in one comparison: a closed flagship still costs roughly seven times more per output token.
4. Distinguishing Legitimate Training from Extraction: Detection and Policy Response
If the central danger is not the existence of open weights but the erosion of the commercial position that funds frontier development, the natural policy question becomes whether the underlying extraction can be detected, deterred and distinguished from legitimate training without banning a technique the entire industry depends on. The difficulty starts with definitions. Distillation, in the technical sense of training a smaller “student” model to mimic the outputs of a larger “teacher” model, is used by American frontier labs on their own systems constantly, to produce cheaper variants for customers. Legal scholars broadly agree that nothing in current intellectual property law makes the practice itself unlawful, since a model’s output, lacking human authorship, generally falls outside copyright protection.[23] What Anthropic characterizes as an attack is not the technique but the mode of access underlying it: coordinated networks of fraudulent accounts, described by the company as “hydra cluster” architectures, in which a single proxy network can manage more than twenty thousand accounts simultaneously, routing traffic through third-party cloud platforms to evade the regional access restrictions that prevent commercial use of Claude within China.[24] That distinction between distillation as a widely practiced training method and distillation carried out through systematic fraud is analytically clean but legally underdeveloped. A breach of a company’s terms of service is ordinarily a civil matter with limited remedies; the fabrication of identities and purpose-built evasion infrastructure to sustain unauthorized access moves the conduct toward statutes such as the Computer Fraud and Abuse Act and federal wire fraud provisions. However, no such case had yet been tested in court as of this writing.[25]
Table 1. Legitimate Distillation Versus Extraction-Pattern Distillation
Dimension
Legitimate Distillation (Standard Practice)
Extraction-Pattern Distillation (Alleged Attack)
Access method
Ordinary paid API access under standard terms of service
Coordinated networks of fabricated accounts routed through proxy infrastructure
Query volume and pattern
Varied, consistent with ordinary product development or research use
Narrowly concentrated on a rival's most differentiated capabilities, at industrial scale
Stated purpose
Producing smaller, cheaper variants of a lab's own models, or legitimate research and evaluation
Systematically reconstructing a competitor's proprietary capabilities without comparable investment
Legal exposure
Governed by ordinary contract and intellectual property law; not itself unlawful
Plausible exposure under the Computer Fraud and Abuse Act and federal wire fraud statutes, though untested in court
Example from the record
Anthropic's and OpenAI's own practice of distilling frontier models into cheaper variants for customers
The campaigns Anthropic attributes to DeepSeek, Moonshot, and MiniMax (Feb. 2026) and to Alibaba's Qwen lab (Jun. 2026)
Note: An analytical distinction, not a settled legal standard; accused firms have denied wrongdoing in every case so far. Source: Compiled from Anthropic, Feb. 23, 2026; War on the Rocks, Aug. 3, 2026
The two disclosed episodes illustrate both the scale of the problem and the limits of unilateral corporate detection. In the February campaign, Anthropic attributed the DeepSeek portion specifically to internal reasoning-elicitation prompts designed to extract Claude’s chain-of-thought training data at scale and traced Moonshot’s activity through metadata that matched the public profiles of the lab’s own senior staff.[26] In the case attributed to MiniMax, Anthropic disclosed that it had detected the campaign while it was still active, before the resulting model had even launched, only to watch MiniMax redirect roughly half its extraction traffic within a day of Anthropic releasing a newer system.[27] The June episode attributed to Alibaba’s Qwen lab was, by Anthropic’s own account, larger than the three February campaigns combined and specifically targeted the software engineering, agentic reasoning and cybersecurity capabilities embodied in Anthropic’s most advanced frontier system.[28] Alibaba has not addressed the specifics of the allegation and no independent party has verified Anthropic’s figures; the entire account rests on the disclosing company’s own forensic analysis, a point War on the Rocks’ Ryan Fedasiuk raised as a genuine due-process concern, since sanctioning a foreign firm on the strength of an accuser’s internal investigation, however credible, sets an uncomfortable precedent for ad hoc adjudication in a market this consequential.[29] Independent trade press coverage of the same disclosure reported matching figures, lending at least secondhand corroboration to Anthropic's numbers even as the underlying characterization remains contested. [30]
Figure 6. Within the disclosed February campaign, one lab did most of the extracting: MiniMax alone accounts for nearly four-fifths of it.
China’s own government has responded in kind rather than engaging the specifics. In July 2026, its Ministry of Commerce accused unnamed American firms of distilling Chinese models. It threatened unspecified retaliatory measures should Washington impose sanctions, offering no company names and no supporting evidence, a mirror-image accusation that suggests both governments now treat the distillation dispute as leverage in a more extensive negotiation rather than as a discrete legal question awaiting resolution.[31] This symmetry is not entirely new. When DeepSeek’s R1 model first triggered scrutiny in early 2025, the incoming Trump administration’s AI advisor David Sacks stated there was “substantial evidence” that DeepSeek had distilled OpenAI’s models, a claim OpenAI’s own memo to Congress echoed a year later regarding continued circumvention of its access controls.[32] What changed between 2025 and 2026 was not the basic dispute but its scale, its formalization in detailed technical disclosures and its entanglement with a parallel and more explosive fact: Anthropic itself had settled a $1.5 billion lawsuit in September 2025 for training its own models on pirated books, a settlement critics on both sides of the debate have cited as evidence that frontier labs’ complaints about unauthorized capability extraction sit uneasily alongside their own record on intellectual property.[33] Some commentators went further, characterizing Anthropic’s distillation disclosures as self-serving alarm dressed up as a national security concern, one prominent critic mocking the idea that a company simultaneously marketed as a technically formidable frontier lab and as a victim unable to prevent unauthorized extraction of its own product.[34]
Figure 7. Set side by side, the two campaigns read less as a steady drumbeat than an escalation, February's "industrial scale" looks modest next to June's.
Set against this contested backdrop, the policy response that has gained the most traction, articulated most fully in War on the Rocks and repeated in Anthropic’s own stated position, rests on four related moves. First, responsibility for verifying an extraction claim should not remain solely with the accusing company; an independent body, potentially the U.S. Center for AI Standards and Innovation, would need to develop the technical capacity to confirm or disconfirm a distillation attack claim, separating conduct that constitutes fraud from conduct that merely constitutes training on data a firm made available, however reluctantly, to the public.[35] Second, sanctions targeting the specific labs found to have engaged in coordinated extraction, whether by Commerce Department Entity List designations, restrictions on U.S. cloud infrastructure access or other instruments, should attach to the fraudulent conduct rather than to the open-weight release itself, since weights already published cannot be unpublished. A ban on the underlying technique is neither enforceable nor consistent with how the American AI industry itself operates.[36] Third, a disclosure requirement, described by one analyst as a nutrition label for the AI supply chain, would require AI services operating in the United States to identify the provenance of their base models and where associated user data is processed, addressing the more mundane but arguably more consequential problem that many American developers are currently building on Chinese models without their own customers’ knowledge.[37] Fourth and perhaps most important from a purely competitive standpoint, sustained public investment in American open-weight alternatives, through instruments such as the long-pending CREATE AI Act, an open-weights track within the National Artificial Intelligence Research Resource or advance government purchase commitments for inference services built on domestically developed open models, would address the reality that developers are choosing Qwen and Kimi not from ignorance but because those models are free, permissively licensed and cheap to serve, qualities any credible American alternative would need to match rather than merely criticize.[38]
None of these measures resolves the basic tension identified in the previous chapter, that frontier labs need pricing power to fund development and that pricing power is precisely what a maturing open-weight ecosystem erodes regardless of its legality. What they can do is separate legitimate competitive pressure, which American policy has no principled basis for suppressing, from fraudulent extraction, which it does. Whether that separation holds in practice depends heavily on frontier labs’ own security posture, a point War on the Rocks pressed with some bluntness: Anthropic’s most restricted model was reportedly accessed by outside hobbyists on a public forum before its official release, during which several hundred fraudulent accounts managed to run millions of queries against it, evidence that the porousness enabling large-scale extraction is not exclusively a function of foreign state actors’ sophistication but also of American labs’ own uneven access controls.[39] A company asking the U.S. government to treat its model outputs as strategic assets carries some obligation to secure them as such before it can credibly ask the state to backstop that security through sanctions.
Figure 8. Accounts barely grew between campaigns, exchanges per account nearly doubled, extraction intensity per identity rising faster than the identities themselves.
5. Conclusion - Reciprocity and the Sustainability of the Open-Weight Commons
An older dispute, unrelated to artificial intelligence on its face, offers a useful, if imperfect, analogy: does the relationship between commercial beneficiaries of an open technology and the community that sustains it need to be reciprocal to remain viable over time and if so, what happens when it is not. The clearest domestic precedent is not from artificial intelligence at all but from the WordPress ecosystem, where roughly a third to just over two-fifths of the world’s websites run on software whose ongoing maintenance depends heavily on voluntary and corporate contribution rather than any licensing fee.[40] In September 2024, WordPress co-founder Matt Mullenweg publicly accused the hosting company WP Engine, then generating a large project, of failing to contribute adequately to its upkeep, calling the firm a cancer on the ecosystem and ultimately blocking its access to WordPress.org’s plugin and update infrastructure entirely, a move a federal court later ordered reversed on preliminary injunction grounds.[41] Automattic subsequently reduced its own contribution to the mutual maintenance effort to match what it characterized as WP Engine’s comparatively modest 50-hour weekly commitment, an unmistakable signal that the party that had historically subsidized the commons was no longer willing to do so unilaterally.[42] The dispute was confused, litigious and, in significant part, personal and it does not map cleanly onto the distillation debate. But the primary structural claim it dramatized, that an open resource sustained disproportionately by a handful of contributors can only remain healthy if commercial beneficiaries return some share of value to its maintenance, translates directly to the AI distillation problem, where the extraction has so far flowed almost entirely in one direction, from labs bearing tens of billions of dollars in training costs toward labs that, according to Anthropic’s own disclosures, have paid nothing beyond the cost of maintaining fraudulent accounts.
It would be an overstatement and not one this paper’s evidence supports, to claim that continued distillation at current rates spells the literal end of frontier AI development, in the way an unmaintained WordPress core might eventually leave hundreds of millions of sites exposed to unpatched vulnerabilities. Frontier labs retain revenue sources, enterprise contracts, government work and increasingly diversified product lines that are considerably more insulated from consumer-facing price competition than the WordPress analogy implies. What is more plausible and better supported by the trajectory traced across the preceding chapters, is a slower and more consequential shift: a frontier increasingly funded by concentrated enterprise and government revenue rather than broad consumer subscription, models released with narrower windows of open access before distillation risk forces tighter restriction and a research culture that grows more secretive precisely as the security case for openness, made forcefully in the industry’s own open letter, becomes harder to sustain in practice. Nvidia, Microsoft and their co-signatories argued in July 2026 that openness itself reinforces security by exposing systems to greater scrutiny and reducing single points of failure, a claim with real merit in domains such as conventional software vulnerability discovery.[43] Amodei’s own rebuttal, that this logic breaks down specifically in domains with a strong offense-defense asymmetry, biological weapons design chief among them, where a capable model might shorten the path towards catastrophic misuse far faster than defensive measures can be assembled, remains, on the evidence available as of this writing, unresolved by empirical testing rather than settled by either side’s assertion.[44]
The evidence assembled here supports a narrower and more defensible conclusion than either the alarmist framing, which treats every open-weight release as a national security emergency or the libertarian framing, which treats every distillation accusation as protectionist cover. What threatens American AI leadership is not the open-weight model as an artifact but the absence of a functioning boundary between legitimate competitive pressure and fraudulent capability extraction, a boundary that neither existing intellectual property law nor voluntary corporate disclosure has yet supplied. Narrowing that gap does not require banning open weights, a step even their most exposed victim, Anthropic, has explicitly and repeatedly declined to endorse. It requires an independent verification capacity that does not depend on the accused party trusting the accuser’s internal forensics, sanctions calibrated to fraud rather than to technical achievement, disclosure rules that let American businesses and their customers know what they are actually building on and a sustained public and private investment in domestic open alternatives capable of competing on the terms, price, license and ease of deployment, that are currently drawing developers toward Chinese models regardless of any accusation leveled against them. Absent that combination, the likely trajectory is neither China’s outright displacement of American frontier labs nor the collapse of AI development altogether. Still, a narrower, more defensive and more consolidated American frontier will be achieved by retreating from the openness that made rapid, distributed innovation possible in the first place.
References
[1] Seetharaman, D., & Arámburo, F. "OpenAI says China's DeepSeek trained its AI by distilling US models, memo shows." Reuters, via Yahoo Finance, February 2026.
[2, 5, 16, 24, 26, 27] Anthropic. "Detecting and preventing distillation attacks." Anthropic News, February 23, 2026.
[3, 28] Digital Applied. "Anthropic Accuses Alibaba of Record Model Distillation." June 27, 2026 (footnote 3 jointly with the following); Novet, J. "Anthropic accuses Alibaba of campaign to 'brazenly' and 'illicitly' extract AI capabilities." CNBC, June 24, 2026.
[4] Villasenor, J. "Why open-weight models are crucial for American AI leadership." Brookings, August 10, 2026; Schuler, M. "China Accuses US AI Firms of Distilling Chinese Models." Implicator.ai, July 27, 2026.
[6, 25, 29, 35, 37, 38, 39] Fedasiuk, R. "How to Stop China from Freeriding on American AI." War on the Rocks, August 3, 2026.
[7] Villasenor, J. "Why open-weight models are crucial for American AI leadership." Brookings, August 10, 2026.
[8, 9, 10] Clark, C. "The Open Weight Models that Matter: June 2026." OpenRouter Blog, June 27, 2026.
[11] "Open Weights and American AI Leadership." Open letter hosted by Microsoft Corporate Responsibility, July 24, 2026 (signatory count as of August 3, 2026).
[12] "AI Update #30: The Distillation Economy." Substack newsletter, May 4, 2026.
[13] Reuters. "China's open-source dominance threatens US AI lead, US advisory body warns." Via Yahoo News, March 23, 2026 (U.S.-China Economic and Security Review Commission report).
[14] Bhusal, M. "Why the AI Subsidy Story Keeps Getting Weaker." Personal blog, April 30, 2026.
[15] "Top American AI execs sound alarm on Chinese models." Via MSN, 2026.
[17] NPR. "Some U.S. startups are turning to cheap Chinese AI models." July 15, 2026.
[18] Bloomberg, via Business Standard. "China's AI advance creates 'death zone' for rival US model makers." August 4, 2026.
[19] 24/7 Wall St. "Anthropic Says Alibaba Used 25,000 Fake Accounts to Copy Its AI, and the Stock Is Already Sliding." June 2026.
[20] Forbes. "Anthropic Says Alibaba Used 25,000 Fake Accounts To Distill Claude." June 26, 2026.
[21, 44] Amodei, D. "Our position on open-weights models." Anthropic News, July 27, 2026.
[22] South China Morning Post. "Jevons Paradox: why China's cheap AI models could be good for Silicon Valley." 2026.
[23] Fedasiuk, R. "How to Stop China from Freeriding on American AI." War on the Rocks, August 3, 2026; NPR. "Allegations of AI distillation spark debate about IP theft. But is it illegal?" July 28, 2026.
[30] Morales, J. "Anthropic claims that China's Alibaba used 25,000 fake accounts and 28.8 million exchanges to illicitly 'distill' its Claude model." Tom's Hardware, June 25, 2026.
[31] Schuler, M. "China Accuses US AI Firms of Distilling Chinese Models." Implicator.ai, July 27, 2026.
[32] "After DeepSeek bombshell, ChatGPT's OpenAI accuses Chinese firms of replicating its AI models." Via Malay Mail, January 2025.
[33] Lichtenberg, N. "Anthropic claims 3 Chinese companies ripped it off, using its AI tools to train their models." Fortune, February 24, 2026.
[34] Techmeme aggregation of reactions to Anthropic's February 2026 distillation disclosure, including commentary from technology critics, February 2026.
[36] Amodei, D. "Our position on open-weights models." Anthropic News, July 27, 2026; Fedasiuk, R. "How to Stop China from Freeriding on American AI." War on the Rocks, August 3, 2026.
[40] Gravitykit. "WordPress powers 33% of the web in 2026 (down from 36% at its peak): CMS market share report." 2026 (HTTP Archive data, with W3Techs-methodology estimates placing total website share above 40%).
[41, 42] Mehta, I. "The WordPress vs. WP Engine drama, explained." TechCrunch, updated January 2025.
[43] "Open Weights and American AI Leadership." Open letter hosted by Microsoft Corporate Responsibility, July 24, 2026.
Why AI War Crimes Accountability Starts With a Missing Defendant
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
Modified
AI reorganizes accountability for war crimes; it does not erase who is responsible
Ukraine shows cameras can prove intent; Gaza shows AI can obscure it
Synthetic media now lets perpetrators deny real evidence, demanding two preserved accountability chains
Two scenes are worth holding side by side. In the first, a row of men sits in a courtroom in 1945, confronted with their own signatures, their own orders, the people who carried those orders out. In the second, a drone circles a building, a model scores the odds that a shape on a screen is a fighter, and somewhere a strike happens with nobody visibly pulling anything. AI war crimes accountability has become urgent partly because these two scenes feel like they belong to different moral universes, and it's tempting to assume the second one lacks a clear answer to the question the first one settled: who did this.
The assumption deserves more scrutiny than it usually gets. The instinct that automation erases responsibility has real philosophical pedigree, but it may be confusing a location problem with an absence problem. The people who decided to build a targeting system, trust its output, and put it into a live conflict zone are, in most cases, still identifiable. How many hands touch a decision, and how far back the real choices happen, is what has changed and how far back in time the consequential choices tend to get made. A war crime that once required someone standing close enough to see a face might now trace back through a procurement office, a training dataset, and a command policy set months before anyone opened a live feed. The chain has gotten longer and harder to follow. Whether it has become untraceable is a separate, harder question, and one this piece takes seriously rather than assuming away.
There's a second, newer complication layered on top of the first, and it may be the more difficult one to solve. Even when the human chain behind a strike can, in principle, be reconstructed, the visual record of what happened is now contestable in ways it rarely used to be. Generative tools can manufacture footage of an atrocity that never occurred, and they can just as easily be invoked to cast doubt on footage of one that did. Both moves push toward the same outcome: a public, and eventually a court, less able to say with confidence what happened and who should answer for it.
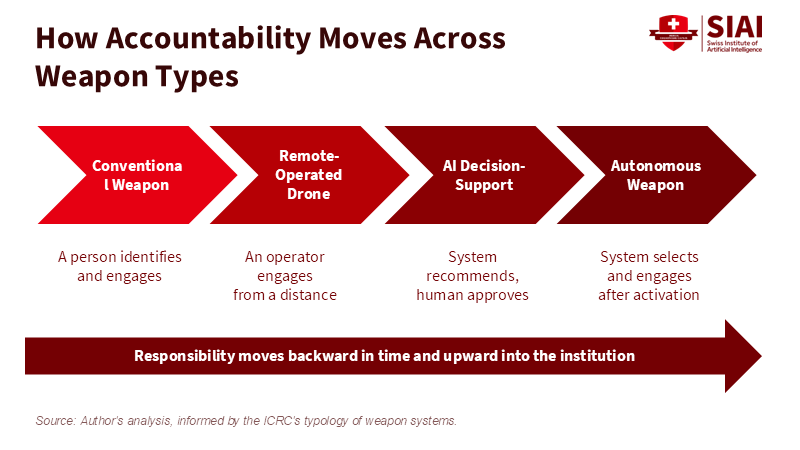
Figure 1: Responsibility does not disappear as weapons grow more autonomous. It moves earlier in time and higher up the chain.
What Nuremberg Actually Proved
Return to that 1945 courtroom for a moment because the lesson people usually draw from it is worth revisiting. The common version says guilt always rises to the top, that the people who give orders bear it and the people who follow them are largely shielded. What the tribunal actually established was narrower, and arguably more useful for the present moment: an institution cannot fully absorb a crime the way a sponge absorbs water. A state can issue an order, but a state cannot be marched into a cell. Someone specific generally has to answer, and depending on what they knew, what they controlled, and whether a real choice was available to them, that someone can sit at almost any level of a hierarchy.
That last part is easy to underweight. Following orders was never treated as an automatic excuse under the postwar principles, but it wasn't treated as an automatic conviction either. The judgment asked what a person actually understood about what they were doing and whether they had meaningful room to refuse. That test was built for humans operating inside bureaucracies, and it translates, imperfectly but usefully, to humans operating inside algorithmic systems. A commander who activates a system with a known error rate, known blind spots, and a known population beneath it hasn't been replaced by that system so much as handed a decision with foreseeable consequences, which is the kind of decision legal systems have long claimed the ability to judge, even if doing so here will take real work.
Ukraine Suggests the Gap Is Often Manufactured, Not Built In
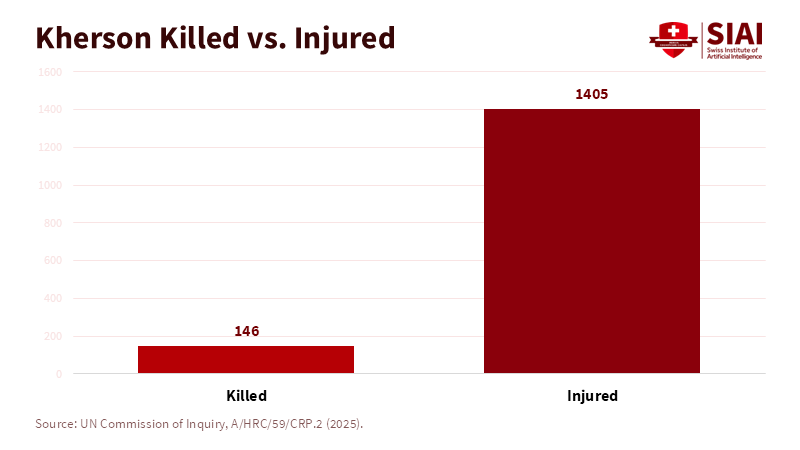
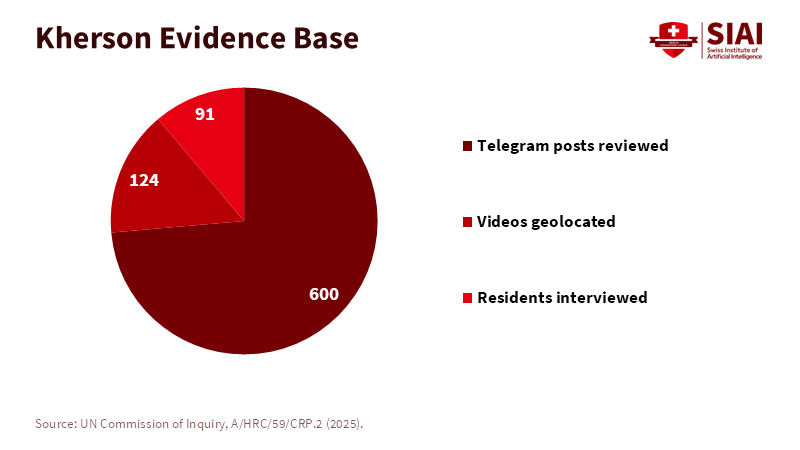
Skeptics of this argument sometimes point to Ukraine as evidence that drones create exactly the kind of anonymity that makes prosecution difficult. What the documentation there suggests is more complicated, and in places points the other way. Investigators looking into a sustained campaign of drone strikes on civilians in one Ukrainian region found operators using commercially available drones, watching their targets clearly enough on camera to identify a woman walking her dog or an ambulance arriving at a scene, and apparently striking anyway. Much of the footage came from channels linked to the units involved, posted in a way that reads less like concealment and more like indifference to being seen.
A camera, an apparent decision, and a surviving record don't look much like an accountability gap in the usual sense. There's a camera, an apparent decision, and a record that survived. What a case like this suggests is that precision and moral distance aren't necessarily the same thing. A system clear enough to let someone spare a civilian is also clear enough to let them target one deliberately, and when that happens, the technology hasn't obviously done much to the underlying chain of responsibility beyond making it easier, in this instance, to document. The pattern won't hold everywhere, but it's enough to show remote weapons don't automatically launder guilt on their own." (removes the duplicate.
Gaza Shows Where the Real Difficulty Sits
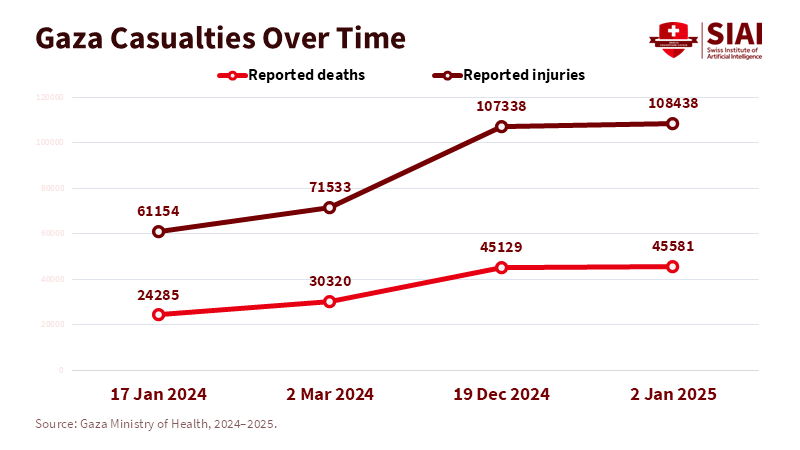
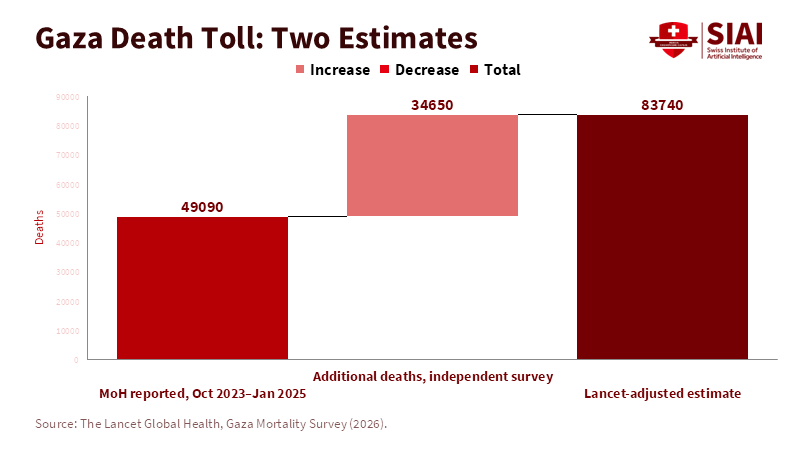
Gaza is the harder case, and it deserves to be treated as genuinely harder rather than waved past. There, by several accounts, artificial intelligence appears to have operated further upstream, generating and ranking lists of potential targets rather than simply assisting someone's aim. Reporting citing military intelligence sources described a system that flagged tens of thousands of names, paired with a review process that, according to those accounts, sometimes amounted to seconds of human attention before a strike was authorized. Independent human rights observers found the reported error rates and review times, if accurate, troubling enough to help explain casualty figures that would be difficult to account for through manual targeting alone.
Those specific claims remain contested, and treating disputed reporting as settled fact would be its own kind of mistake. The underlying question survives however the details eventually resolve. Even in a fairly charitable reading, humans built the target-generation system, humans set the threshold for how much verification a strike required, and humans apparently decided that speed mattered more than scrutiny in at least some cases. Very little of that decision belongs to the software itself. The temptation to say the algorithm did it is exactly the move any serious account of AI war crimes accountability probably needs to resist, since it's the one that lets responsibility drift upward and outward until it lands nowhere in particular.
The Second Front Few Frameworks Are Ready For
Even a carefully reconstructed chain of human decisions runs into a newer obstacle, one most legal frameworks weren't built with in mind. Convincing synthetic images and video have made it possible, at least in principle, to deny real atrocities simply by asserting, plausibly enough, that the evidence is fabricated. A government or armed group no longer necessarily has to disprove a photograph. It may only need to seed enough public doubt that the photograph gets treated as unreliable, which can quietly shift the burden of proof onto grieving families and independent investigators rather than the people responsible for what happened.
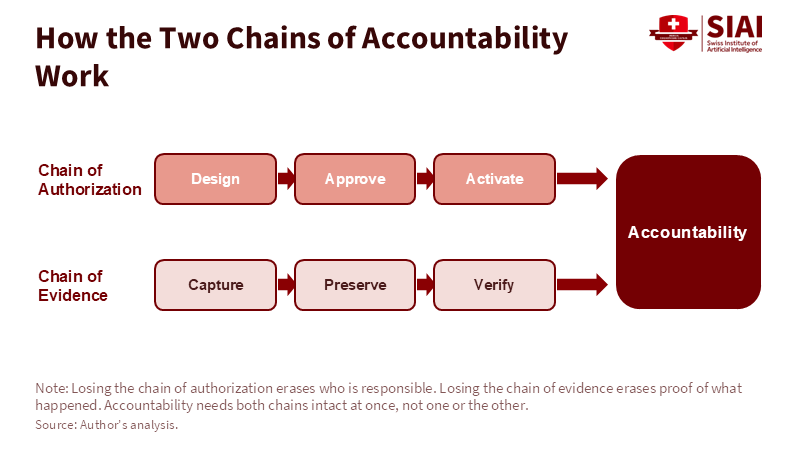
Figure 2: Authorization tells you who to blame. Evidence lets you prove it. Losing either one is enough to break accountability.
This is part of why a serious approach to accountability probably has to protect two separate threads at once rather than one. The first is a record of who designed, approved, and activated a given system, kept in a form resilient enough to survive an institution's later attempt to muddy it. The second is a record of what actually happened on the ground: images, logs, testimony, ideally authenticated before anyone has the chance to flood the space with convincing fakes. Losing the first thread tends to make responsibility hard to locate; losing the second makes it hard to prove even once it's been found. Modern conflict seems to be testing both threads at roughly the same time, which is a reasonable argument for treating them as one problem rather than two separate ones.
None of this suggests new weapons make accountability impossible. It suggests accountability now depends more than it used to on preserving records deliberately, rather than assuming they will simply exist. That looks like a solvable problem, though probably only if the people building and deploying these systems are treated, from the outset, as the ones responsible for solving it.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
The Machine Cannot Stand Trial: Responsibility for War Crimes in the Age of AI
Published
SIAI Research Editorial*
*Swiss Institute of Artificial Intelligence, Chaltenbodenstrasse 26, 8834 Schindellegi, Schwyz, Switzerland
Abstract
AI-enabled warfare is widely imagined as a domain in which responsibility dissolves, where a drone approaches, an algorithm classifies and the destructive act occurs so far from any human hand that no one can plausibly be blamed. This paper argues that this picture is mistaken. AI does not eliminate human agency in war; it rearranges and obscures it. Drawing on the Nuremberg principles, the contemporary practice of international humanitarian law, the documented conduct of remote and algorithmic warfare in Ukraine and Gaza and the moral psychology of distance and killing, the paper contends that accountability has to follow meaningful control, knowledge, foreseeability, legal duty and the capacity to prevent harm, not physical proximity to the victim. It develops a five-part responsibility test and applies it across the full chain of actors, from political leaders to operators to designers and procuring states. It then confronts a second, compounding danger: generative AI not only fabricates wartime content but produces a condition of ambient uncertainty in which authentic evidence can be dismissed as synthetic, yielding what has been termed a liar's dividend for perpetrators. Establishing responsibility in AI-enabled warfare therefore requires preserving two chains simultaneously, the chain of authorization and the chain of evidence. The greater danger is not that machines become guilty but that institutions use machines to make human guilt harder to locate and harder to prove.
1. Introduction - The Courtroom Without a Defendant
In the Palace of Justice at Nuremberg between 1945 and 1946, responsibility had a face and a name. The architects of aggression and atrocity sat in an identifiable row, confronted with their own signatures, their own directives, the testimony of those who had carried out their orders and the paper trail of an institution that had organized killing on an industrial scale. Whatever one thinks of the tribunal's contested legality, its central achievement was choreographic as much as jurisprudential. It placed particular human beings in a defined physical relationship to the crimes charged against them and refused to let the abstraction of the state absorb their guilt. The contrast with contemporary AI-enabled warfare is stark. A loitering drone approaches a building; a classification model scores the probability that a figure on a screen is a combatant; a decision-support system ranks a list of dwellings and recommends an order of attack; and the destructive act, when it comes, may occur with no one visibly pulling a trigger and no single moment at which a human being looked upon the victim and chose. If such a system unlawfully kills civilians, someone must still be identified to sit in the defendant's chair.
That identification is harder than it first appears and it is tempting to conclude that no one can be found. The intuition that automation creates a void of responsibility has a distinguished philosophical pedigree and it is precisely the intuition this paper sets out to reject. The conventional framing treats the problem as a novel metaphysical puzzle about machines, whether an algorithm can be blamed, whether code can bear guilt, when the more urgent problem is institutional and moral. AI distributes human agency across more hands, pushes it earlier in time and buries it deeper inside organizations, with the practical effect that responsibility becomes harder to locate rather than actually absent. The correct analytical response traces the human decisions that gave the machine its authority: who chose to build it, who chose to trust it, under what conditions, with what knowledge and with what capacity to intervene.
A second problem compounds the first and recent work has made it unavoidable. Even where human responsibility remains traceable in principle, the evidentiary environment in which it would be proven is now under systematic assault. Generative AI injects false images and fabricated footage into wartime information flows and beyond that, it manufactures a pervasive condition of doubt in which authentic documentation can be waved away as synthetic. Research published by the Carnegie Endowment for International Peace in mid-2026 describes the risk of this doubt becoming the permanent condition of modern war documentation.[1] It produces what legal scholars have called the liar's dividend, the benefit that accrues to a wrongdoer not only from passing off fakes as real but from passing off the real as fake, since widespread awareness that fake content exists has made false claims of fake news easier to sustain.[2] When Iran's foreign minister posted an authentic photograph of rows of freshly dug graves after strikes that Iranian authorities reported had killed around 170 people, at least 110 of them schoolchildren, opposition accounts immediately labeled the image AI-generated. By the time the image was verified as genuine, the doubt had already spread and the burden fell on grieving families to prove that their dead were real.[3]
The two accountability problems are distinct but mutually reinforcing. The first concerns who is responsible when an AI-enabled system contributes to an unlawful attack. The second concerns whether that responsibility can be established at all once the surrounding evidence can be manipulated, flooded or pre-emptively discredited. The second problem has been documented far more concretely than the first. The mechanics of evidentiary sabotage are visible in Gaza, Tigray, Sudan and Iran, while the chain of responsibility inside an algorithmic kill chain remains mainly theoretical and shielded by classification.[4] The cast of potential defendants is long. It includes the political leader who authorized the campaign and set its tolerances; the commander who selected the operational policy and the classes of target; the officer who approved a particular strike; the operator who activated the system; the intelligence analyst who accepted the machine's recommendation; the programmer who built the targeting model; the firm that sold it; and the state that procured, reviewed and deployed it. The task of this paper is not to convict any of them in the abstract but to establish the principles by which responsibility should be allocated among them, principles that, as the next section argues, were substantially settled three-quarters of a century ago and have merely been made harder to apply.
2. What Nuremberg Actually Established
Before Nuremberg, the grammar of international wrongdoing was collective. States waged war, armies committed excesses, governments pursued policies and the individuals who directed these entities could shelter behind the official character of their acts. The International Military Tribunal broke this grammar with a holding that has been quoted ever since: "Crimes against international law are committed by men, not by abstract entities and only by punishing individuals who commit such crimes can the provisions of international law be enforced."[5] The significance of this holding was not that it invented accountability for cruelty but that it relocated it, from the fictional person of the state to the actual persons who used the state as their instrument.
The principles distilled from the Charter and Judgment by the International Law Commission in 1950 are compact and remain the conceptual foundation of the field.[6] A person who commits an act constituting a crime under international law is responsible and liable to punishment. The absence of a domestic penalty does not relieve that responsibility. Acting as head of state or as a responsible government official confers no immunity. Acting under superior orders does not relieve responsibility so long as a moral choice remained genuinely possible for that person. Complicity in such a crime is itself a crime. Read together, these propositions accomplish three things at once. They substitute individual responsibility for institutional abstraction; they establish that responsibility can attach at several levels of a hierarchy rather than at only one; and they imply, through their careful conditioning, that not every death in war and not every act of a subordinate is automatically criminal. Responsibility tracks conduct, knowledge, participation, authority and the availability of a genuine choice.
It is worth dwelling on what the superior-orders provision does and does not say, because it is routinely misread. It does not abolish the relevance of orders; it denies them the status of an automatic excuse where a moral choice remained open. The standard is calibrated, not blunt. It concentrates the heaviest responsibility on those who designed and administered organized criminal violence, the architects and senior functionaries who set policy and issued directives, without thereby granting automatic absolution to those who executed them. The executioner is neither presumptively guilty nor presumptively innocent; his position on the chain of command is evidence, not verdict. Later codifications preserve this structure and sharpen it. The doctrine of command responsibility, expressed in Article 28 of the Rome Statute, holds a military commander criminally responsible for crimes committed by forces under effective command and control where the commander knew or should reasonably have known given the circumstances at the time, that the forces were committing or about to commit such crimes and failed to take all necessary and reasonable measures to prevent or repress them.[7] This "should have known" standard is a negligence standard. A commander who receives repeated reports of unusual civilian casualties in a unit's area of operations cannot escape by cultivating ignorance.
The lesson most often drawn from Nuremberg, that guilt rises automatically to the highest office, is only half right. What the tribunal actually established was more durable and more demanding: institutions cannot make individual human responsibility disappear. Bureaucracy, hierarchy, technical specialization and the invocation of orders are precisely the ways through which responsibility is diffused until it seems to belong to no one and the entire point of the Nuremberg settlement was to deny that diffusion its exculpatory power. AI-enabled warfare now tests this same principle, because the algorithm is a new and unusually effective diffuser. If a machine can be inserted between the decision and the death, the temptation is to treat the machine as the terminus of responsibility, the point at which the human chain runs out. The remainder of this paper traces who, on a chain of algorithmically mediated killing, should still be summoned to answer.
3. Remote Warfare Can Save Soldiers While Making Killing Easier
Distance has always been the great solvent of the reluctance to kill. The military psychologist Dave Grossman argued in his study On Killing that resistance to killing declines as the distance between attacker and victim grows, from the visceral difficulty of edged-weapon combat to the near-frictionless ease of releasing ordnance from altitude.[8] Drones and remote systems extend this trajectory. They let a state see less blood and seeing less blood, they may make killing easier to authorize and easier to repeat. Any honest account of AI-enabled warfare has to hold this paradox steadily in view, because the technology's genuine benefits and its genuine dangers flow from the same source.
The benefits are real and should not be minimized in order to score a rhetorical point. Reconnaissance drones gather intelligence without exposing personnel; remotely operated systems reduce the need to send soldiers into heavily defended areas; machine vision can, in some conditions, classify objects more consistently than an exhausted or frightened operator; and a properly constrained system, bounded by tested parameters, could in principle improve precision and reduce impulsive firing. Fewer soldiers may die during reconnaissance, targeting and certain attack operations. These are not trivial considerations and a policy that ignored them in order to preserve an older and bloodier image of honorable combat would be morally unserious.
What AI-enabled warfare actually encompasses deserves precision, because the public debate tends to collapse distinct technologies into a single specter. The International Committee of the Red Cross, in its position paper on autonomous weapon systems, defines such systems as weapons that, once activated, can select and engage one or more targets without further human intervention: systems in which, after a human sets them in motion, the application of force is triggered by environmental inputs matched against a generalized target profile.[9] This is a narrow category and much of what is called AI in contemporary war falls outside it. Machine-vision classifiers, pattern-of-life analytics and decision-support systems that recommend or select targets for human approval are, on the ICRC's own account, distinct from autonomous weapons proper. The umbrella term is useful precisely because it spans this range but the analysis must not blur the differences, since responsibility attaches differently at each point. What unites the category is the ICRC's central and, here, decisive position: it is humans, not machines, who must determine the lawfulness of an attack and that determination cannot be delegated to a machine process.[10] The legal judgment is non-transferable. A machine may perform technical tasks but the determination that a strike complies with distinction, proportionality and precaution is a context-specific human assessment for which the human remains accountable.
The following table locates the accountability concern that predominates at each level of mediation and it warrants attention because the concerns are not the same.
Table 1: Accountability Across Levels of Weapon Mediation
System type
Target identification
Final engagement
Principal accountability concern
Conventional weapon
Human
Human
Orders, intent and conduct of an identifiable actor
Remotely operated drone
Human operator
Human operator
Distance may obscure the operator and the command chain behind the screen
AI decision-support system
AI recommends or prioritizes
Human formally approves
Automation bias and superficial human review that is legally present but operationally hollow
Autonomous weapon
System selects and engages after activation
Machine process within human-set parameters
Responsibility shifts to the design, review and authorization that preceded deployment
The movement down this table is a movement of responsibility backward in time and upward into the institution. It does not describe a leak of responsibility out of the human world; it describes its migration. This is where the paradox bites hardest. The very automation that spares one side's soldiers can, on the other side, enable more killing rather than less, because the same industrial acceleration that removes friction from the attacker's decision multiplies the number of targets that can be generated, processed and struck in a given period. Saving soldiers and allowing faster, larger-scale destruction of the adversary's people and infrastructure are not competing descriptions of the technology; they are two faces of a single capacity. What matters is not whether the capacity is used but whether the humans who wield it retain and exercise the judgment the law requires.
Figure 1. Deaths and injuries have moved together, not apart; the ratio between the two lines is the real story here, not the slope of either one alone.
4. Actual Cases
4.1 Ukraine: Drones Do Not Necessarily Mean Autonomous Killing
The war in Ukraine is often invoked as the proving ground of a new autonomous age but its most rigorously documented drone atrocities point in almost the opposite direction. In a conference-room paper of 28 May 2025, the UN Human Rights Council's Independent International Commission of Inquiry on Ukraine concluded that Russian armed forces had committed the crime against humanity of murder and the war crime of attacking civilians through a months-long pattern of drone strikes on the right bank of the Dnipro River in Kherson Province. The Commission documented attacks across Kherson city and sixteen other localities over a stretch of more than one hundred kilometers, in which, by the official sources it cited, nearly 150 civilians had been killed and hundreds more injured. Its findings rested on interviews with 91 residents, the geolocation of 124 of more than 300 publicly available attack videos and the review of over 600 text posts on Telegram channels.[11] The perpetrators used commercially available civilian drones weaponized to drop explosives, as well as first-person-view suicide drones, all equipped with cameras letting operators to track and aim remotely.
Figure 2. Roughly ten injuries for every death is a signature of sustained, deliberate targeting rather than isolated error.
The evidentiary detail that matters most for the present argument is this: the drone footage, much of it posted by the perpetrating units themselves on Telegram channels, showed that the perpetrators could clearly see the victims, leaving no doubt that they intended to target civilians.[12] Here is remote warfare in which distance created no accountability gap whatsoever. The operator saw a woman walking her dog, a hospital employee arriving at work and an ambulance and struck anyway. The command structure was identifiable, the organizational policy inferable from the pattern's scale and duration and the intent legible from the operators' own cameras. Ukraine therefore demonstrates two things at once. Technological precision does not guarantee civilian protection; a camera that lets an operator distinguish a civilian perfectly well is also a camera that lets him target one deliberately. And the remoteness of a weapon does not, by itself, dissolve responsibility. Where the human remains in the loop and the record survives, the operator and those who directed him remain as accountable as any rifleman. The accountability gap, where it exists, is manufactured, not intrinsic.
Figure 3. Almost none of it came from official disclosure, it was built from what the perpetrators posted themselves.
4.2 Gaza: AI Decision Support and the Acceleration of Targeting
Gaza presents the harder case, because there the reported role of AI sits upstream of the trigger, in the generation and ranking of targets rather than the firing of weapons. An investigation published by the Israeli-Palestinian outlet +972 Magazine and Local Call in April 2024, based on the testimony of six Israeli intelligence officers, reported that the Israeli military used a system named Lavender that identified as many as 37,000 Palestinians and their homes as suspected militants and possible strike targets; a related system reported earlier, The Gospel, generated building and infrastructure targets. Sources told the outlet that personnel devoted roughly twenty seconds to each target before authorizing a bombing, often merely confirming that the marked individual was male, despite knowing that the system's classifications were erroneous in an estimated ten percent of cases.[13] The Israeli military rejected the reporting, its spokesperson describing the tools as auxiliary aids that assist officers and require independent analyst confirmation and stating that the systems do not autonomously select targets for attack.[14]
These claims must be characterized with care, because they are contested and their legal weight depends on their accuracy. The reporting rests on anonymous testimony and has not been adjudicated. Independent UN human rights experts, however, took it seriously enough to state in April 2024 that the reported use of systems such as Gospel, Lavender and Where's Daddy, combined with lowered human due diligence, would, if accurate, help explain the extraordinary toll in Gaza, noting that more than 15,000 deaths occurred in the first six weeks, when AI systems appear to have been most heavily relied upon.[15] The responsible analytical posture is to treat the specific mechanics as reported and alleged rather than established, while recognizing that even the uncontested contours, that AI systems accelerated target generation and that humans retained formal although compressed review- are sufficient to frame the accountability question. What must be resisted is the slide from "AI helped generate targets at scale" to "the machine decided," because that slide is exactly the exculpatory move this paper exists to refuse. As the journalist behind the investigation stressed, the decision to bomb private homes systematically was made by humans; the AI let a deadly practice be multiplied at scale.[16]
Figure 4. The gap between the two bars is larger than the entire original count.
4.3 Distance, Scale and Moral Inhibition
Beneath the legal argument runs a moral-psychological one that the Gaza and Ukraine cases jointly illuminate. Traditional frontline violence forces the soldier into the human reality of killing, with all the resistance and residue that Grossman documented. Remote warfare removes the attacker from physical danger and AI-assisted targeting can go further, removing the decision-maker from psychological confrontation with the individual victim altogether. When a target arrives as a name on a ranked list with a probability value and a narrow window for approval, the deliberative encounter that once attended the choice to kill is replaced by an act of validation. The more targets a system produces, the less time any human spends examining each one. Careful judgment degrades into industrial processing and the twenty-second review becomes not an aberration but the predictable equilibrium of a system optimized for tempo.
Yet the moral psychology is more ambivalent than a simple thesis of moral disengagement would allow and honesty requires accepting the complication. Interviews with British Reaper crews conducted by Peter Lee show that physical distance does not reliably produce emotional distance.[17] Documented rates of post-traumatic stress and what researchers term moral injury among remote drone operators point the same way.[18] The high-resolution camera that enables killing from half a world away also compels the operator to watch the blast, the survivors, the bodies gathered into blankets and to return to the same screen the next day. The relevant distinction is not physical but epistemic and moral distance, which surveillance technology can paradoxically narrow even as it extends physical range. This ambivalence does not rescue the technology; it sharpens the argument. The danger of AI-enabled targeting is not that every operator becomes a callous button-pusher but that the institution can be designed to minimize the moments of confrontation that generate moral friction and to distribute the decision so widely that no individual experiences himself as the author of the death. Technology can reduce one kind of brutality, the sacrifice of soldiers, while enabling another: more frequent, faster and emotionally insulated applications of force. The absence of blood on the operator's hands does not mean no human decision occurred; more likely, the decision was made earlier, farther away and inside a more complex institution.
5. Who Should Be Blamed When an Algorithm Contributes to an Unlawful Killing?
A machine cannot be a moral defendant. The philosophical literature that first raised the responsibility gap, most influentially Robert Sparrow's 2007 argument that no one can be fairly held responsible for the wartime acts of a genuinely autonomous system, since neither the programmer nor the commander could predict its behavior and the machine itself cannot be punished, identified a real puzzle but drew from it a conclusion that does not follow.[19] Sparrow's own remedy was that systems like that should therefore not be deployed. But the systems in use today are not the fully autonomous agents of the thought experiment. They are decision-support tools and human-supervised weapons whose behavior, while imperfectly predictable, is foreseeable in exactly the way the law requires. Later philosophers have argued that a commander who activates a system knowing it will operate autonomously and knowing that error isn’t simple possible but statistically certain satisfies both the control condition and the foreseeability condition for moral responsibility.[20] The gap closes because the human who empowered the machine never ceased to be responsible for it. The question is which humans decided to give the system authority, under what conditions, with what knowledge, with what safeguards, not whether the algorithm is guilty.
5.1 Responsibility Test
Rank and job title alone should never determine conviction, because they are proxies for the things that actually ground responsibility rather than the things themselves. Five factors do the real work. The first is causal contribution: how directly and substantially the person's act or omission contributed to the unlawful attack. The second is knowledge and foreseeability: what the person actually knew and what a reasonable person in that role should have anticipated. The third is meaningful control: whether the person could authorize, halt, modify, or prevent the operation, a concept first proposed by the non-governmental organization Article 36 in 2013 to describe control over a weapon's critical functions of selecting and engaging targets, which subsequently migrated into the wider ethics of AI.[21] The fourth is legal and institutional duty: whether the person was charged with reviewing, supervising, or constraining the system. The fifth is intent and acceptance of risk: whether the person intended the unlawful outcome or knowingly accepted an unlawful risk. These factors are cumulative and weighted rather than a checklist to be tallied. A low causal contribution paired with high knowledge and a clear duty may ground more responsibility than a high causal contribution undertaken in excusable ignorance.
Political and military leadership occupy the position where the highest-command intuition is strongest and most defensible. Leaders who establish unlawful targeting policies, who authorize indiscriminate or foreseeably disproportionate operations, who remove or hollow out meaningful human review in the name of tempo, who ignore recurring and reported civilian harm or who fail to investigate and discipline known violations bear responsibility that no downstream automation can discharge. If a policy sets an acceptable civilian toll per target category, the wrongfulness of the resulting deaths originates in that policy, not in the model that populated the target list. The model executed a tolerance that human leaders chose. This is the precise sense in which those who construct the operational system cannot escape by pointing to the final operator or the machine.
Operational commanders and strike authorizers usually stand closest to the legally decisive deployment decision and the ICRC's analysis of autonomous systems maps their duties with unusual precision. Because the user of such a system cannot know in advance which specific person or object will trigger a strike, the commander must assess lawfulness prospectively, at the moment of activation, across the entire area and duration of the system's operation and in light of all reasonably foreseeable changes in circumstances.[22] This translates into a demanding set of responsibilities: selecting the environment in which the system is used, restricting the classes of target, setting geographic and temporal limits, assessing proportionality and precautions, judging whether the system is sufficiently predictable to be used at all and canceling or suspending the attack when circumstances change.
Operators and intelligence analysts should not be presumed guilty and they should not be presumed innocent either and here the concept of the moral crumple zone is indispensable. The anthropologist Madeleine Elish uses the term to describe how, in complex automated systems, responsibility for a failure is misattributed to the human operator who in fact had limited control over the system's behavior. The human becomes a component that absorbs the moral and legal responsibility when the overall system malfunctions, while the integrity of the technical system and of those who designed and deployed it, is protected.[23] A twenty-second reviewer, given no real authority or time to reject the machine's output, is a candidate crumple zone. Blaming him alone would replicate the very injustice the concept warns against. The relevant considerations are specific: whether the analyst knowingly approved a civilian target, whether reliable contrary evidence sat before him, whether he was permitted sufficient time and genuine authority to reject the system's recommendation or whether rejection was institutionally discouraged and whether he intentionally disregarded visible signs of civilian presence. Automation bias, the well-documented human habit of over-trusting and under-scrutinizing automated recommendations, can reduce a nominal human decision to a rubber stamp while the paperwork still records a human choice. It is a genuine institutional and psychological phenomenon and it cuts in two directions.[24] It mitigates the individual operator's culpability where the institution engineered the conditions for it and it aggravates the culpability of those who designed those conditions knowing what they would produce.
Designers and manufacturers require the most careful distinctions, because the intuitions here are the least reliable. Building a targeting algorithm is not, in itself, the commission of a war crime, any more than designing a missile makes an engineer responsible for every unlawful launch. The default position must be that the programmer is neither the presumptive villain nor categorically immune. Potential responsibility arises, however and international criminal law's doctrines of complicity and aiding and abetting can reach it, where a designer or firm builds a system specifically to facilitate unlawful targeting, knowingly conceals dangerous defects, falsifies accuracy or safety results, continues to provide essential assistance while knowing the system is being used for criminal operations or intentionally strips out the safeguards required for lawful use. The precedents are sparse but real. Post-war tribunals convicted industrialists and national courts have convicted businessmen such as the Dutch traders Frans van Anraat and Guus Kouwenhoven for aiding and abetting atrocities through the supply of means.[25] The threshold is demanding. The Rome Statute limits the Court to natural persons and its aiding-and-abetting standard requires that assistance be rendered specifically to facilitate the crime, a stringent mental-state requirement that a profit-motivated firm can often plausibly deny but it is not empty.[26]
Figure 5. Coverage tracks geopolitics more than geography: near-universal in Eastern Europe, barely a third of Asia-Pacific.
States, procurement bodies and reviewing institutions bear a responsibility that precedes the battlefield entirely and it is codified. Article 36 of Additional Protocol I to the Geneva Conventions provides that "in the study, development, acquisition or adoption of a new weapon, means or method of warfare, a High Contracting Party is under an obligation to determine whether its employment would, in some or all circumstances, be prohibited" by international law.[27] This obligation is broad. It reaches acquisition, not only development, so a purchasing state cannot outsource the judgment to the manufacturer's home country and it is widely regarded as binding on all states regardless of treaty ratification, because it follows reasonably from the prohibition on using unlawful weapons. Article 36 thus creates institutional responsibility upstream of any operator's decision. A state that fields an AI-enabled system whose effects it cannot understand, predict and explain has failed a legal duty before a single strike occurs. The concrete demands that follow from taking this seriously are specific and assignable: pre-deployment legal review of the kind Article 36 requires, tested and documented operational limits, traceable command authorization for each deployment, preservation of system logs, documented override and cancellation procedures and independent post-strike investigation.
Figure 6. Opposition didn't grow between 2023 and 2024 — it shrank, even as the technology matured.
5.2 Generative AI and Atrocity Denial
Suppose, however, that every link in this chain of authorization could in principle be traced. A second technology now works to ensure that it cannot be proven. The generative AI that produces synthetic images and video adds falsehoods to the wartime recor and worse, degrades the evidentiary value of the entire record, because once convincing fakes are known to exist, every authentic document becomes vulnerable to the accusation that it, too, is fabricated. This is the liar's dividend described earlier: bad actors benefit not only from passing fakes off as real but from passing real evidence off as fake.[28] The mechanism is now visible across theatres. In Gaza, an authentic photograph of an injured man at Al-Shifa Hospital was doctored with an AI-added third leg and then circulated as supposed proof that images of Palestinian victims are generally AI-generated; a displaced man raising money online was accused of being an AI creation on the strength of garbled text on a mass-produced blanket and spent hours proving he was real.[29] In Iran, a separate AI-generated image of blood-soaked streets, posted by a partisan commentator and swiftly debunked, nonetheless served the regime's interest by lending credence to the claim that all documentation of a real massacre was suspect.[30] In Tigray, communications blackouts achieved the older version of the same end, making documentation dangerous or impossible, while AI now achieves it in a decentralized, industrial form available to anyone with a model and an account.[31]
The critical insight is structural: an AI-generated lie need not survive verification to succeed. The accusation does not need to persuade; it only needs to plant enough doubt that the truth arrives already damaged. Sometimes the corruption runs the other way, with authentic footage paired with a deceptive frame, as when real video from a militarized aid site was deployed as propaganda and then, when accused of being synthetic, defended by forensic analysts who found no sign of AI even as the political framing around it remained a lie. The accusation of fakery has, in this environment, no fixed target. It is a weapon available to every party and it escapes the control of those who first reach for it. The harm, meanwhile, is concentrated on specific and identifiable people: the parents burying children whose graves are called synthetic, the survivor forced to prove his own existence, the witness whose evidence is discredited before it is even examined.
The implication for accountability is that AI-era responsibility must preserve two chains at once and neither suffices alone. The first is the chain of authorization: who designed, approved, procured, deployed, supervised and activated the system, recorded in a form that can survive institutional denial. Without it, responsibility becomes diffuse to the point of vanishing, exactly as the machine's defenders intend. The second is the chain of evidence: how targeting data, system outputs, human approvals, strike logs, images and testimony were recorded and preserved. Without it, responsibility may exist in principle but cannot be proven in practice. The two chains fail in complementary ways. An institution can defeat accountability either by diffusing the decision until no author remains or by degrading the record until no proof survives. This is why practical remedies now emerging from the human-rights and open-source-investigation communities, provenance and content-credential infrastructure embedded at the point of capture, distributed and tamper-resistant archives, chain-of-custody standards such as the Berkeley Protocol on Digital Open Source Investigations and protections for the physical safety of those who document, are not peripheral technical housekeeping but the evidentiary counterpart of the Nuremberg principle itself.[32]
6. Technology Changes the Weapon, Not the Need for Judgment
Return, then, to the courtroom. Nuremberg's lasting lesson was never merely that senior leaders can be punished. It was that organized institutions cannot transform human crimes into ownerless events, that layers of hierarchy and technical specialization cannot turn a superior order into an excuse that erases any single author. AI-enabled warfare revives this temptation in a new and more sophisticated form. Its logic surfaces in the anticipated chorus of mutual deferral: the commander blames the model, the operator blames the recommendation, the programmer blames the user, the manufacturer blames the state, the political leader blames an operational failure and the state, reaching for the newest instrument of all, dismisses the very evidence as synthetic. Each move is individually plausible. Together they amount to a mechanism for manufacturing impunity, the same mechanism Nuremberg was built to dismantle, now re-tooled.
Figure 7. Almost all the growth happened in the Court's first decade; the last fifteen years added almost nothing.
The counterarguments deserve better than dismissal, because at their strongest they are correct as far as they go. Remote and AI-enabled weapons can indeed spare soldiers who would otherwise be sacrificed and it would be morally simplistic, even perverse, to demand that human beings be exposed to danger merely to preserve an older and more heroic image of war. Automation can, under the right constraints, reduce certain impulsive human errors. And it is true that warfare has always been technologically mediated, that the drone is in one sense only the latest point on a continuum that runs from the sling to the artillery piece. These arguments establish that AI-enabled warfare is not uniquely evil and need not be categorically prohibited. What they do not establish is that removing people from the frontline may also remove human decision-making from the decision to kill. The continuum of mediation is real but it has always been accompanied by a continuum of responsibility that tracks control, knowledge and duty rather than proximity. The artillery officer beyond sight of his target was never thereby absolved. The novelty of AI is not that it mediates but that it can be made to obscure and the appropriate response is to insist that the obscuring be undone: that logs be kept, reviews be genuine, authorizations be traceable and evidence be preserved.
Figure 8. Support hardened rather than softened between the two votes; the opposite of what backroom pressure usually produces.
The weapon has changed. Responsibility has not vanished. A machine may identify a target and even trigger the attack but human institutions decided to build it, chose to authorize it and placed living people within its reach. Those decisions are where the moral weight resides and they are made by people with names. The machine cannot stand trial. The people who gave it that power still can.
7. Conclusion - Accountability for AI-Enabled War Crimes
The reframing this paper has urged is simple but consequential. AI-enabled warfare does not create a void of responsibility; it creates a diffusion of responsibility and the two are easily confused because they look alike from the outside. The apparent void is an artifact of institutional design, of decisions distributed across many hands, pushed backward in time and buried inside organizations. It can be undone by the same means Nuremberg used against the abstraction of the state: by insisting that crimes are committed by people and by tracing the chain of human decisions that gave the machine its authority. Responsibility should follow meaningful control, knowledge, foreseeability, legal duty and the capacity to prevent harm, applied without sentiment across leaders, commanders, operators, designers and states and calibrated by the recognition that the nearest human operator is often the least culpable, not the most.
The evidence assembled here supports a precise policy conclusion rather than a general exhortation and the international machinery to act on it already exists in embryo. In October 2023 the UN Secretary-General and the President of the ICRC jointly called on states to conclude negotiations on a legally binding instrument on autonomous weapons by 2026. In December 2024, the General Assembly adopted Resolution 79/62 by 166 votes to 3, with only Belarus, North Korea and Russia opposed. Since January 2023, United States doctrine has required that certain systems allow commanders and operators to exercise appropriate levels of human reasoning over the use of force. The task is to give these commitments teeth. Because responsibility in AI-enabled warfare fails in two distinct ways, through the diffusion of the decision and through the degradation of the proof, the governing requirement must be that both chains be preserved by law and by design: a chain of authorization traceable to named individuals at every step and a chain of evidence preserved against both fabrication and denial. Concretely, no AI-enabled system whose effects cannot be understood, predicted and explained should pass an Article 36 review; human review must be resourced with the time and authority to be genuine rather than a rubber stamp; system logs, override records and post-strike investigations must be mandatory and independently auditable; and provenance infrastructure and protected archives must be treated as instruments of accountability. The machine cannot be blamed and it cannot be believed or disbelieved on its own authority. Only people can be and the work of law and policy is to ensure that when an algorithm kills unlawfully, the people who gave it that power can still be found, named and judged.
References
[1, 3, 4, 29, 30, 31] Alimardani, M. and Rigot, A. (2026) Generative AI and Atrocity Denial in War. Washington, DC: Carnegie Endowment for International Peace.
[2, 28] Chesney, R. and Citron, D. (2018) 'Deep Fakes: A Looming Challenge for Privacy, Democracy, and National Security', California Law Review, 107, pp. 1753–1819.
[5] International Military Tribunal (1946) Judgment of the International Military Tribunal for the Trial of German Major War Criminals. Nuremberg: IMT.
[6] International Law Commission (1950) Principles of International Law Recognized in the Charter of the Nürnberg Tribunal and in the Judgment of the Tribunal. New York: United Nations.
[7, 26] United Nations (1998) Rome Statute of the International Criminal Court. The Hague: International Criminal Court.
[8] Grossman, D. (2009) On Killing: The Psychological Cost of Learning to Kill in War and Society. Rev. ed. New York: Back Bay Books.
[9, 10, 22] International Committee of the Red Cross (2025) Autonomous Weapon Systems and International Humanitarian Law: Selected Issues. Geneva: ICRC.
[11, 12] United Nations Human Rights Council, Independent International Commission of Inquiry on Ukraine (2025) "They Are Hunting Us": Systematic Drone Attacks Targeting Civilians in Kherson, A/HRC/59/CRP.2. Geneva: OHCHR.
[13, 14, 16] Abraham, Y. (2024) 'Lavender: The AI Machine Directing Israel's Bombing Spree in Gaza', +972 Magazine, April.
[15] Office of the United Nations High Commissioner for Human Rights (2024) Gaza: UN Experts Deplore Use of Purported AI to Commit 'Domicide' in Gaza. Geneva: OHCHR.
[17, 18] Lee, P. (2018) Reaper Force: The Inside Story of Britain's Drone Wars. London: John Blake.
[19] Sparrow, R. (2007) 'Killer Robots', Journal of Applied Philosophy, 24(1), pp. 62–77.
[20] Himmelreich, J. (2019) 'Responsibility for Killer Robots', Ethical Theory and Moral Practice, 22(3), pp. 731–747.
[21] Article 36 (2013) Killer Robots: UK Government Policy on Fully Autonomous Weapons. London: Article 36.
[23, 24] Elish, M.C. (2019) 'Moral Crumple Zones: Cautionary Tales in Human-Robot Interaction', Engaging Science, Technology, and Society, 5, pp. 40–60.
[25] Bryk, L. and Saage-Maaß, M. (2019) 'Individual Criminal Liability for Arms Exports under the ICC Statute', Journal of International Criminal Justice, 17(5), pp. 1117–1137.
[27] Diplomatic Conference on the Reaffirmation and Development of International Humanitarian Law (1977) Protocol Additional to the Geneva Conventions of 12 August 1949 (Protocol I). Geneva: ICRC.
[32] Human Rights Center, University of California, Berkeley and Office of the United Nations High Commissioner for Human Rights (2022) Berkeley Protocol on Digital Open Source Investigations. Berkeley: UC Berkeley.
The AI Premium Is About Implementation, Not Access
Picture
Member for
2 years
Real name
Keith Lee
Bio
Keith Lee is Professor of AI and Finance at the Gordon School of Business and Head of Research at the Swiss Institute of Artificial Intelligence (SIAI). His research focuses on financial mathematics, AI-driven computational science, and quantitative modeling of complex economic and financial systems, integrating machine learning, stochastic modeling, and data-centric methods.
His recent work examines the socioeconomic consequences of artificial intelligence, including labor markets, public finance, demographic change, institutional adaptation, and the distributional effects of technological progress.
He also serves as Executive Editor, Research & Review at The Economy, overseeing research-oriented editorial coverage, analytical contributions, and engagement with academic and industry specialists.
He holds a PhD in Mathematical Finance from Boston University, an MSc in Finance and Economics from the London School of Economics, and a bachelor's degree in Economics from Seoul National University, where he studied under the Korea Foundation for Advanced Studies scholarship program.
Published
Modified
AI access is common; implementation creates value
Deeper AI use carries a stronger market signal
Future advantage will depend on workflow redesign and outcomes
In the first four months of 2024, weekly AI token consumption on one major routing platform sat in the billions. By April 2026, it had climbed past 15 trillion tokens a week, a cumulative jump of roughly 1,362 times in just over two years. That is the kind of number that makes AI adoption sound like a settled fact. Yet the same period produced surveys in which most companies claimed to be using AI, while most also reported no measurable change in productivity or staffing. Those two realities are not in conflict. They describe different things: how much AI capability exists in the world and how much of it has actually been built into the way a company works. That distinction is exactly what recent stock market evidence on the AI premium has started to price.
The Measurement Problem Behind AI Access
Corporate AI use gets counted in ways that blur together very different situations. A firm can be labeled an adopter because one employee has a chatbot license, because a single department redesigned a workflow around model output or because software has been wired directly into company data and decision systems. Official statistics tend to flatten these into one figure. Eurostat found that just under 20 percent of European Union firms with ten or more employees used at least one AI technology in 2025, while a narrower measure of AI actually used in production put the figure closer to 7 percent in the United States and 4 percent in the European Union. Federal Reserve researchers have pointed out that this kind of gap makes it hard to separate incidental experimentation from adoption that actually changes how work gets done. A cross-country survey of more than 5,000 senior executives captured the same disconnect directly: around 70 percent of firms reported active AI use, while more than 80 percent reported no effect on productivity or employment over the prior three years.
That combination, widespread reported use alongside limited measured impact, looks less like AI failing to deliver and more like an implementation lag. Buying access to a model is now cheap and fast. Connecting that model to real data, real workflows and real accountability structures is neither. Firms still need to decide who can use a model, what data it touches, how outputs get checked and who is responsible when something goes wrong. Those tasks resemble the kind of complementary investment that earlier general-purpose technologies also required before their productivity effects became visible in the numbers. Their current scarcity is part of what current asset prices appear to be reflecting.
Figure 1: AI access creates potential; economic value emerges as models become embedded in production.
Nominal adoption figures amplify the confusion further once different surveys are placed side by side. One federal business survey put AI use at roughly 18 percent of firms once the question was broadened to cover any business function, while a separate employment-weighted survey produced a figure near 78 percent and a worker-level survey landed closer to 41 percent. Much of that spread comes down to differences in how the question is asked and how responses get weighted, rather than any real disagreement about how AI is being used. Corporate announcements suffer from a related problem. A statement that a company has launched an AI strategy could describe anything from a completed production redesign to an early budget line and mention counts in regulatory filings cannot tell those apart on their own.
What the AI Premium Actually Rewards
Recent asset-pricing research gives that idea a concrete test. Rather than relying on survey answers, one 2026 study built a market factor directly from realized AI consumption recorded through an API routing service between January 2024 and April 2026, covering roughly 380 trillion tokens across more than 400 models. Firms whose stock returns moved most closely with growth in that consumption factor went on to earn meaningfully higher returns than firms with low exposure, with a value-weighted spread of about 64 basis points per week in the baseline estimate. That spread is the empirical core of the AI premium described here. That spread held up after controlling for technology-sector exposure, semiconductor returns, AI-themed funds and public attention.
What matters for corporate strategy is how that signal changed with the type of consumption behind it. Exposure built from frontier, closed-source models produced a much stronger return spread than exposure built from open-weight usage. The same pattern showed up for paid and long-tenured accounts against new ones and for long, complex prompts against short ones. Casual and entry-level use barely moved the needle, while sustained, experienced, technically demanding use moved it substantially.
That gap is a more useful way to separate genuine deployment from superficial subscription counts than any binary yes-or-no adoption question could manage, since seat counts and registered users cannot tell a company that quietly builds real workflows around a model apart from one that lets its licenses go unused after an initial trial.
It is worth being precise about what a positive premium actually means here. It is a statement about the return investors require for taking on AI-related exposure, not a guarantee that markets assign higher present value to AI-heavy firms. A higher expected return can reflect stronger growth prospects, greater risk or both and technological shifts often raise uncertainty for exactly this reason: investors are still learning which businesses will benefit and which will not.
The signal also does not appear to be a short-lived reaction to headlines. Around frontier model releases, high-exposure firms outperformed low-exposure firms by roughly 1.9 percent over a five-day window, yet the broader spread persisted even after those release weeks were removed from the sample. Geography adds a further layer. The spread was a statistically meaningful 17.9 basis points per week in developed markets, while the corresponding emerging-market estimate was close to zero. That pattern is consistent with pricing being strongest where firms, investors and infrastructure sit closest to the technological frontier, rather than proof that firms in developed economies are inherently better at putting AI to use.
Implementation as the Scarce Input
The occupational pattern behind this premium reinforces the implementation story. Positive market-implied AI exposure clusters around installation, repair, programming, persuasion and other systems-oriented skills, while analytical, scientific and operations-control skills sit on the negative side. That does not mean installation work is permanently worth more than analysis. It more likely reflects where the current bottleneck sits. Before machine-generated analysis can be produced and used at scale, someone has to build the pipes: connect models to data, define access rules, train staff and design the checks that make outputs trustworthy. Field evidence backs this up in pieces. AI assistance raised issue-resolution rates for customer-support agents by 15 percent, concentrated among less experienced workers, while a controlled trial with experienced open-source developers found tools slowing them down on complex, familiar codebases. A workplace collaboration experiment at Procter and Gamble found that individuals working with AI could match the performance of two-person teams. None of these results point in one direction. Together, they show that the value of a model depends entirely on how it is wired into a specific task, not on the model itself.
Firm-size patterns tell a similar story. In 2025, just over 55 percent of large European Union enterprises reported using at least one AI technology, against roughly 30 percent of medium firms and 17 percent of small ones. Eurostat links that gradient to implementation complexity and the fixed costs of building the surrounding organizational capacity, not to differences in access to the underlying technology. A model endpoint can be purchased in an afternoon. The systems, training and internal trust needed to use it productively cannot.
Where the Premium Goes Next
This is where the current pattern of skill exposure should be read as a snapshot of an early phase rather than a fixed hierarchy. Installation, repair and systems-integration skills carry the strongest positive exposure to the AI factor today, while science and operations-control skills sit furthest on the negative side. As enterprise platforms, connectors and evaluation tooling become standardized, the scarcity behind that installation premium should fade. Once most firms can wire a model into their systems with similar ease, that step stops separating leaders from followers and competitive advantage should shift toward what firms actually do with the resulting capacity: which tasks get delegated to models, how outputs get verified and how much expensive analytical work gets replaced without a loss in decision quality.
Figure 2: As implementation standardizes, the advantage shifts toward workflow redesign and measurable value capture.
Underneath that shift sits a governance question companies will need to answer regardless of how standardized the tooling becomes. Generative outputs are plausible rather than fixed and their reliability varies by task and context. Checking every output erodes much of the cost advantage AI is supposed to deliver, while checking too little accumulates risk quietly until it surfaces somewhere expensive. Getting that balance right will matter more as analytical work itself becomes cheap to produce and responsibility for a decision cannot be handed off to a model along with the analysis behind it. That is why coordination, judgment and persuasion stay valuable even as raw analytical output becomes commoditized.
The jump from billions to trillions of tokens a week describes how much AI capability now exists in the economy. It says very little about which firms have turned that capability into lower costs, faster decisions or better outcomes and the market evidence so far agrees: it is the depth and sophistication of use, not the scale of access, that carries pricing information today. The practical takeaway for any company evaluating its own AI strategy is straightforward. Counting licenses or usage claims will not reveal much. What will matter, now and increasingly over time, is whether AI has actually been built into how decisions get made and work gets done.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
2 years
Real name
Keith Lee
Bio
Keith Lee is Professor of AI and Finance at the Gordon School of Business and Head of Research at the Swiss Institute of Artificial Intelligence (SIAI). His research focuses on financial mathematics, AI-driven computational science, and quantitative modeling of complex economic and financial systems, integrating machine learning, stochastic modeling, and data-centric methods.
His recent work examines the socioeconomic consequences of artificial intelligence, including labor markets, public finance, demographic change, institutional adaptation, and the distributional effects of technological progress.
He also serves as Executive Editor, Research & Review at The Economy, overseeing research-oriented editorial coverage, analytical contributions, and engagement with academic and industry specialists.
He holds a PhD in Mathematical Finance from Boston University, an MSc in Finance and Economics from the London School of Economics, and a bachelor's degree in Economics from Seoul National University, where he studied under the Korea Foundation for Advanced Studies scholarship program.
Three internal capabilities, not AI access, decide who captures its value
Firms must judge, measure and govern how much work depends on AI
Most AI pilots show no return, proving access alone guarantees nothing