SIAI GSB Professor Keith Lee to Speak at OEB 2026 in Berlin on AI and the Future of Education
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
SIAI GSB Professor Keith Lee to Speak at OEB 2026 in Berlin on AI and the Future of Education
Keith Lee, Professor of AI and Finance at the Gordon School of Business, Swiss Institute of Artificial Intelligence (SIAI), will present his research on artificial intelligence, labour markets, and education policy at OEB 2026 (Online Educa Berlin), taking place from December 2–4, 2026, in Berlin, Germany.
OEB is an international conference on digital learning and training, bringing together researchers, educators, policymakers, and industry professionals to examine developments in education and workforce development. The 2026 conference, themed Sovereign Learning: Trust, Agency & the Education Reset, focuses on how education systems should respond to structural changes driven by artificial intelligence and other emerging technologies.
Beyond Retraining: Education in the Age of Superhuman Labor
Professor Lee's presentation, "Beyond Retraining: Education in the Age of Superhuman Labor," will take place on December 3, from 12:45 to 13:15, at the conference's Spotlight Stage in Potsdam III.
The presentation examines the limitations of conventional workforce retraining policies as AI systems become increasingly capable of performing complex cognitive and professional tasks.
Current education and employment policies frequently assume that technological disruption produces temporary skills mismatches that can be addressed through retraining. Professor Lee's research challenges this assumption, arguing that continuously improving AI capabilities may require a more fundamental reconsideration of how professional competence is developed and maintained.
The session will explore the distinction between AI-assisted productivity and independent human understanding, emphasizing the importance of domain knowledge, critical reasoning, professional judgment, and the ability to evaluate intelligent systems.
The presentation forms part of SIAI's broader research on artificial intelligence, technological change, and their socioeconomic implications.
Conference details
Event: OEB 2026 — Online Educa Berlin
Dates: December 2–4, 2026
Presentation: December 3, 12:45–13:15
Session: Beyond Retraining: Education in the Age of Superhuman Labor
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Why AI’s Navier-Stokes Proof Is Not Causal Reasoning
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
Modified
AI proofs succeed because Lean checks every step
Agents still return silent errors in routine econometrics
Causal claims have no checker inside the system
On 8 September 2026, OpenAI announced that an internal system had proved that the Navier-Stokes equations can develop a singularity in finite time, solving an open question that has been open for about ninety years. This was achieved by about 10,000 agents working collaboratively over 88 hours. Weeks later, an experiment tested 40 standard econometric tasks and found that agents writing, running and debugging their own code still worked without any warning to produce wrong answers, including for computations that would be simple for a graduate student in economics. These two results only seem inconsistent if one equates mathematical proof with empirical causal reasoning. In fact, they are verified in very different ways, which explains why a system that can prove a Millennium Prize Problem can still need someone to verify a basic regression.
The Significance of the Execution Loop Over the Prompt
The experiment for the econometrics was designed with unusual care. 40 tasks, always one method from linear regression, difference-in-differences, instrumental variables, regression discontinuity, discrete choice, survival and time-series, always in three levels of autonomy (a chatbot which writes the code but does not run it, a self-repairing agent which can be revised up to three times and an agent that runs, checks and revises when necessary) and always a prompt with and without an example. In 14,400 runs, accuracy rose from 79 to 97 percent once the model could execute its code; an example in the prompt improved accuracies for the chatbot by 5.8 to 7.3 percentage points and for the agent by only 0.7 to 1.5 and for one of the two models, the difference between Stata and Python fell from 25.5 to 1.3.
Prompt engineering, which has received a lot of attention in recent years, doesn't seem to matter much once the model can see what its code actually does. This is a different set of questions against which to judge the abilities of these tools: not how well they are prompted to do well on the tests, but a question of the entire research setup, the interpreter, the error messages and the chance to fix them, rather than a language model installed in a chat window. OpenAI's experiment came from a similar setup: thousands of agents running code, with a cached internet and a mechanical proof checker, creating a multi-component system. As autonomy grows, the phrasing of the prompt matters less and the environment becomes more relevant when a failure is met. A feedback loop can only ever improve to the extent it has access to information and the experiment defines the bounds of that information.
Elimination of Loud Errors While Silent Errors Persist
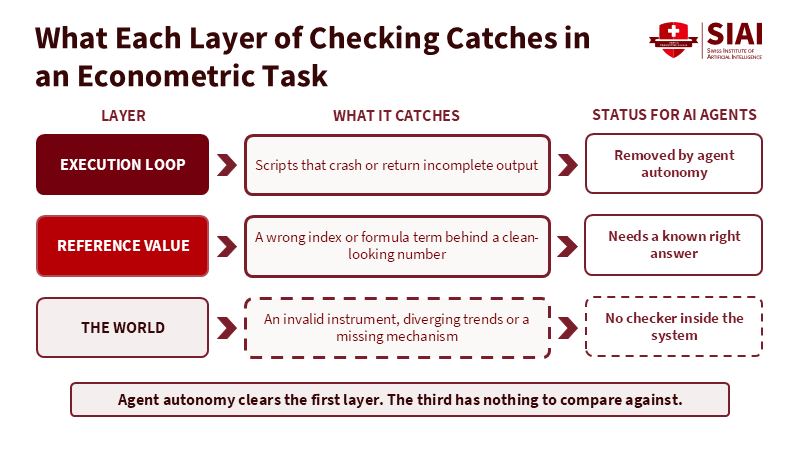
The experiment separates failures into two classes. A loud failure occurs when the script is not run at all, or runs with partial output, producing an error message or null output visible to the researcher. A silent failure occurs when the script successfully runs, produces complete output and still has one or more errors. Loud failures fell from 15.8 per 100 scripts under the chatbot to 0 under the agent, while silent failures fell from 4.9 to 2.9, leaving only silent errors. Over two-thirds of silent failures tested arose from a simple bug in a correct formula or code for where to look it up; an incorrect index or incorrect term in a formula. The most common failure mode was in shift-share IVs where every estimate was returned, but the standard errors fell outside the tolerance.
The agent was specifically asked to check its work in some other way and errors made were exactly those that did not cause any sort of signal through the execution environment. Greater autonomy means doing more and more things until an error signal is processed, if there is a signal, a compiler error or a missing column then the loop finds it and repairs it. In the absence of such a signal, the same wrong number turns up again and it is the human who knows the right number (or at least knows not to rely on the wrong one) to check it and that knowledge is not in the script and much of the time it is also not in the data.
A Method Fails to Assess Causal Reasoning
Nonetheless, it is worth putting the 97 percent figure in perspective. Each problem set up the task such that the model was given the method, a data set simulated by someone else and a reference result computed beforehand, so that the successful run returned the reference value for the task within a given tolerance level. The test was whether the procedure was executed faithfully. Whether the procedure provided a plausible causal estimate was outside the scope of the test. For simulated data, the identifying assumption was necessarily correct as the data had been generated by someone, while for actual research that same assumption was more contentious and no reference point is available ex post. Given legislation that changes hours worked or wages, the researcher may have no idea how the data were generated and thus must rely on an identification argument.
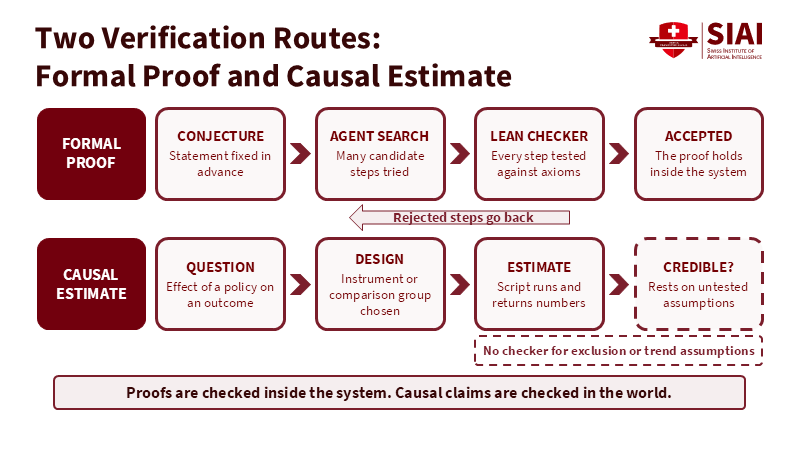
A correctly specified instrumental variables regression will not demonstrate that the instrument passes the exclusion restriction. A perfectly applied difference-in-differences estimator will not demonstrate parallel trends and a significant coefficient will not solely demonstrate a causal channel; these are statements about the universe outside the data, about what would have occurred in the absence of the treatment, or if the instrument were to have had a different value and no interpreter can validate them. A pre-trend test can accept parallel trends even as they diverge at the point of intervention and an overidentification test makes the assumption that at least one instrument is valid, leaving the problem displaced rather than resolved. Thus a broken identification argument is the classic silent failure: the script runs, the coefficient is estimated accurately, the standard error is right, yet the estimate is causally meaningless.
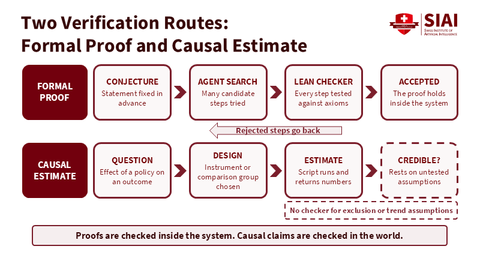
Figure 1: Agent autonomy clears crashes, but identification failures meet no checker.
The True Nature of OpenAI's Solution
The result from OpenAI addresses the forced case. It builds a vortex that converges inward and lengthens in such a way that the velocity blows up in finite time, but the energy remains finite, establishing C and D from the Clay formulation (the unforced versions remain unsolved). The agents that solved the puzzle communicated 2.7 million messages and produced around 130 billion output tokens, plus another 17 hours of formal verification in Lean, which make up the bulk of the result. Lean checks each step to ensure it's a logical consequence of earlier established axioms and theorems and an argument either compiles cleanly or fails to compile. Meaning that failures in a mathematical proof are potentially detectable.
Figure 2: The proof route ends at a checker; the causal route ends at untested assumptions.
Within this domain, the single step of a checker-guided search has all the requisite ingredients: millions of exchanges, thousands of parallel searches, methods borrowed from the universe of connected problems (the Euler solution thrown to the agents as a starting seed) and a checker that is tireless and never fails to see the logical fissures. The mosaic is precisely the same as the one that raised the success rate of econometrics to 97 percent, run on a vastly greater scale and with a perfect error detector. It's pattern matching, no longer the crude form of next-word prediction but pattern generating, testing and pruning at a scale no human can match in 88 hours. And every step is accepted on the ground that the checker allows it to stand; not a single step in the whole edifice requires imagining a counterfactual. The statement of the announcement itself admits that real water cannot flow infinitely fast, so the singularity is where the formulae stop describing the water and the proof offers us a crisp understanding of the formulae but no clue as to how water actually flows down the pipe.
The Limits of Pattern Recognition and Verification
After September 8, the initial interpretation was that artificial intelligence has now crossed a threshold to reason about physical systems and might also for the first time cross over into the causal reasoning of the social sciences. The evidence from econometrics adjusts this interpretation. The tasks in which these systems are good all are amenable to mechanical assessment, whether via a Lean or by reference number within tolerance and no progress is made where the judge no longer exists, even on problems that are facile from a mathematical research perspective. A typical error within a shift-share regression, which is a far easier problem than a Millennium Prize Problem, persisted because there was no system notification to write home about. This doesn't dampen the mathematical achievement, but instead pushes back from how strong the system is and towards what it requires in order to verify itself; the nature of its verification system is very different for the demonstration of a fluid proof versus an estimation of the impact of a minimum wage on employment.
The simplest test would be to give an agent an actual data set without a reference result and see if the alleged instrument passes the exclusion restriction. It may have provided a perfectly plausible argument, but there is nothing in the setup that can attest to its veracity. The 88 hours of OpenAI and the 2.9 silent errors per 100 runs describe the same machine, limited by its checker: in one domain the checker is perfect, in the other it is nonexistent. Whether one can design a verifier for assumptions is still an open question and the nearest approach, the randomized experiment, is subject to real-world costs and time and cannot be run inside a code execution environment.
This article reflects the analytical judgment of the author and does not constitute policy advice or the official position of any affiliated institution.
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
SIAI GSB Professor Keith Lee to Present on AI and Productive Longevity at Fondazione Giorgio Cini in Venice
Picture
Member for
1 year 4 months
Real name
SIAI Editor
Bio
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
Published
Professor Keith Lee of the Swiss Institute of Artificial Intelligence (SIAI) will participate as an invited speaker at the Humankind and Longevity symposium, hosted by Fondazione Giorgio Cini in Venice, Italy, from 19 to 21 November 2026.
Professor Lee will present “AI and Productive Longevity: Redesigning Work for an Ageing Society,” examining how artificial intelligence may extend the productive life of human capital by complementing accumulated professional expertise, reshaping workforce requirements, and supporting organisational innovation.
The presentation will address the economic implications of AI adoption in ageing societies, including workforce adaptation, lifelong learning, and the relationship between technological change and human productivity.
Organised by Fondazione Giorgio Cini, the three-day international symposium brings together researchers and experts from multiple disciplines to examine the biological, social, economic, political, and ethical dimensions of longevity.
Professor Lee's participation follows his presentation at the Foundation's Inequalities in Longevity conference in July 2026, where he discussed “Unemployed Growth and the Emerging Inequality of Longevity.”
SIAI Editor is the institutional editorial identity of the Swiss Institute of Artificial Intelligence (SIAI). It covers research and analysis across AI policy and governance, economics and finance, law and regulation, workforce and education, scientific applications, computational methods, infrastructure, and the strategic adoption of artificial intelligence.
Publications under SIAI Editor are prepared or coordinated by SIAI’s research and editorial team and include research synthesis, policy and industry analysis, technical interpretation, and interdisciplinary work connecting artificial intelligence with established fields of research and professional practice.
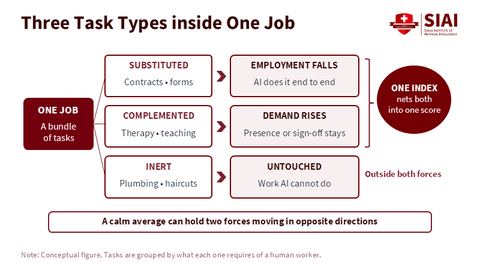
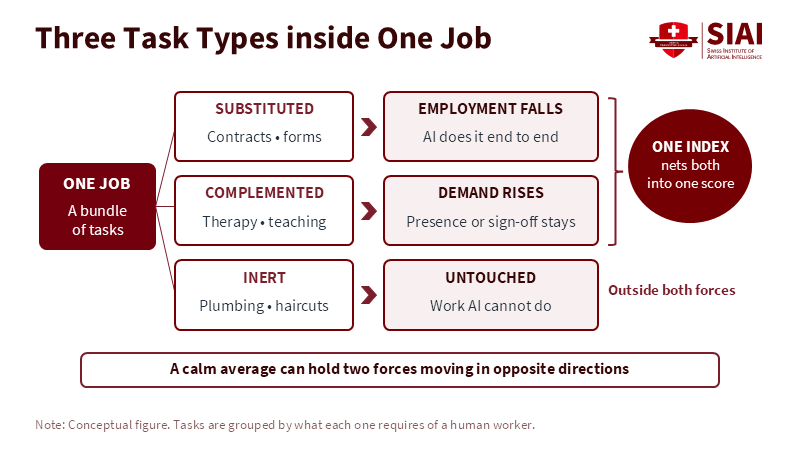
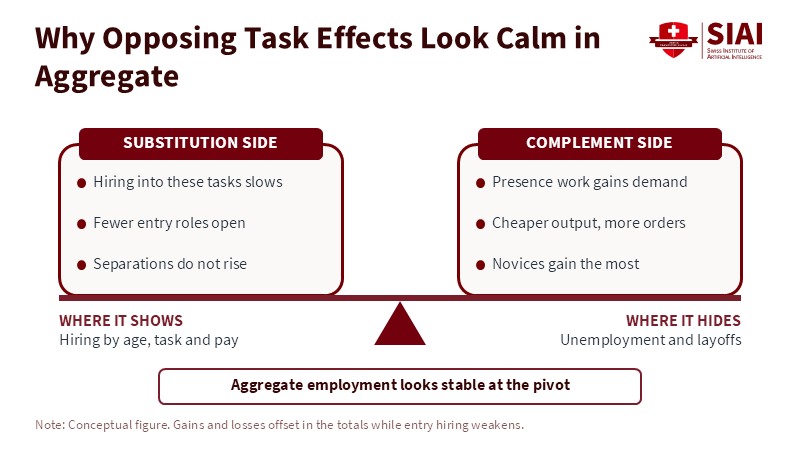
AI removes some tasks while creating demand elsewhere
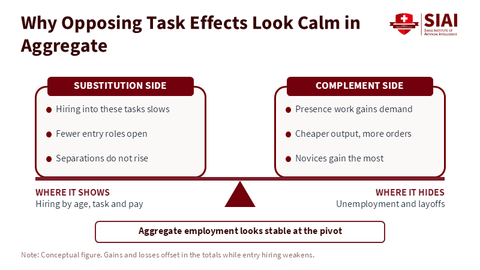
Single exposure scores hide these opposing task effects
Hiring of young workers falls while aggregates stay calm
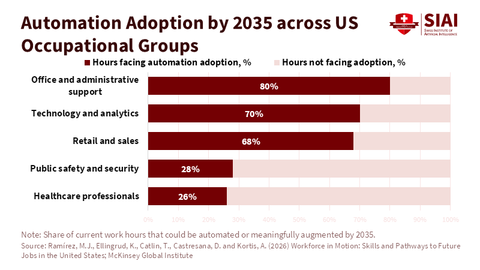
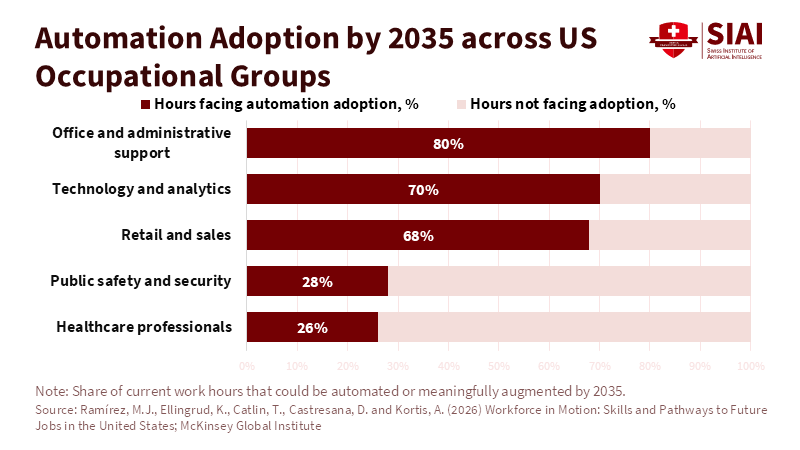
Automation Adoption by 2035 across US Occupational Groups
Picture
Member for
2 years
Real name
SIAI Chart
Bio
SIAI Chart
Input
Modified
Figure 1: Office support faces three times the automation exposure of healthcare professionals, which is why the first losses land on desks rather than wards.